Category: VariCS
Week Beginning 19th January 2026
I worked on many different projects this week, but the one I spent the most time on was the Dictionaries of the Scots Language. I’ve not done much work for the DSL since the intensive period I spent developing the new website interface and deploying it on our test server ahead of the face-to-face meeting in mid-November. I had a list of further updates I needed to make following on from this meeting, but I needed to work on other projects since then and hadn’t got around to it. I’d also received a number of emails about changes to the presentation of entries reflecting the structural changes to the entry XML that I’d put to one side.
On Wednesday I had an online call scheduled with the DSL team to discuss the new front-end and it seemed like a good opportunity to get back to grips with all of my outstanding DSL tasks. This mainly involved making updates to the XSLT on our test server to tweak the layout of various items in the new entry XML structure, such as adding commas between tags when they are rendered, ensuring certain tags or attributes that weren’t getting rendered before appeared in the generated HTML, updating the styles of certain elements like the content warning labels, fixing a few bugs such as the ‘sticky’ heading not displaying in certain circumstances. There were at least 20 such items that needed investigating, fixing and testing, so this took quite some time to work through, but I managed to complete it all during the course of the week.
The meeting itself was very useful and as always it was good to catch up with some of the other DSL team members. There’s going to be a big push towards getting the new website interface ready for publication this year, and I’m obviously going to be involved in this process. I already have a number of items I need to sort out with the new interface and I’ll try and get started on these over the coming weeks.
I also spent a bit of time this week working for the Anglo-Norman Dictionary, investigating a strange occurrence with the publication of updates to entries, which turned out to be a user rather than a system issue, reinstating the links out from entries to the DMF dictionary, as their website is now properly back online again, and tweaking the wording of the quick search and ‘jump to entry’ text throughout the site.
I also did small amounts of work for several other projects, such as updating the licensing statements across the Seeing Speech and Star sites, fixing an issue with the ‘download song’ facilities on the Editing Robert Burns site, sorting an issue with the HiMuJe Malabar site, submitting my expenses from the Zurich workshop, exporting some SCOSYA data for Jennifer Smith, helping to sort out an issue with the Helsinki Corpus, and having a conversation with Clara Cohen about a new proposal she’s putting together. I also made some further updates to the VARICS look-up system, adding in some introductory text, some further references, and reworking the measurement processing so that when a red or amber result is given new textual sections about what this means and what the next steps should be appear underneath in collapsible accordion sections.
Also this week I had a meeting with the Burns Supper Map team to discuss the data that is now coming in and how and when I should start working on a new interactive map to visualise it. I also put in a request for a new subdomain for the project that was set up by the end of the week. Next week I’ll probably write a brief specification document for the front-end.
My final project of the week was the Place-names of Armagh project, for which I started working with some existing place-name data for the area. There are around 230 place-names and several thousand historical forms and I spent quite some time researching how the data was structured and how it might be mapped onto the Glasgow place-names system. This included analysing the geospatial data, including shapefiles for Townlands and what I though was Parishes (but actually turned out to be the same as for Townlands). I had hoped to be able to import the data by the end of the week, but my analysis of the data raised a lot of questions that still need to be addressed, and I’ll need to continue with this next week.
Week Beginning 12th January 2026
This was my first proper week back at work, having spent most of last week travelling and attending a workshop in Zurich. I spent a bit of time working on the Bilingual Thesaurus of Everyday Life in Medieval England, looking into issues that had cropped up at the workshop. Someone had spotted that the start and end dates for some lexemes appeared to be the wrong way round and last week I discovered there were 197 such cases. I had an ongoing discussion with the project PI Louise Sylvester about this. She sent me a spreadsheet that contained updated data for the thesaurus, with the idea being that we could check the erroneous dates against this. However, the spreadsheet was created for a later project than the BTH and had both a different structure and different data. For example, some categories in the online BTH were not included and many categories in the spreadsheet featured different or larger numbers of lexemes. The dates were in a different format, featuring ‘ante’ and ‘circa’, plus a question mark to denote other uncertainty and a plus to denote continuation. The BTH features none of this – just start and end dates. The spreadsheet also featured no links out to the MED and the AND, only links to the OED. We did wonder whether we should replace the online BTH with the data from the spreadsheet but all of these issues mean this just wouldn’t work. Instead we decided that I would (at some point) write a script to identify lexemes in the spreadsheet that are not in the online BTH and we can see about incorporating them. In the meantime I fixed the 197 lexemes that had their dates the wrong way round.
Also for the BTH this week I implemented an option to order the lexemes in a chosen category alphabetically, by first attested date or length of attestation (within the AN or ME section), where previously all lexemes were ordered alphabetically within each section. This is something that was raised at the workshop, and something I wanted to implement as it’s a useful feature. I’d already included this option in the main HT and parts of the code for it were lurking in the BTH code in an inactive state, although I needed to rework this as the main HT handles dates in a more complex manner. The update required changes to the database, the CSS, the PHP and the JS scripts, but it’s all now live and the site remembers your choice during your session, so if you select ‘length of attestation’ in one category and then navigate to another this is remembered. Below is a screenshot showing a category with the lexemes ordered by length of attestation:
This week I met with Jennifer Smith to discuss the talk we’re giving about Speak For Yersel in Edinburgh in a couple of weeks. We had a good chat and made a plan about writing our respective sections. I then spent about a day preparing the slides and text for my section and sent everything over to Jennifer so she could work on her parts.
Also this week I did a little bit of work for the AND, updating links from AND entries to the DMF, as their site has changed, which broke all our links. I thought I’d found a way to link through to their corresponding entries but unfortunately their URLs now include a session variable that expires after a while, and the URL doesn’t work without a valid session. This means it’s not currently possible to link to their entries so for now I’ve had to remove the links. Apparently they are working to fix things so hopefully we’ll be able to reinstate the links at some point.
On Friday I met with Deven Parker to discuss her Playbills project and the requirements document I sent her before Christmas. We discussed a few issues that had been raised in the feedback on the document and made a plan for the coming weeks, during which I will begin to work with the data and will start developing the online resource.
Other tasks I tackled this week included replacing the data I’d uploaded for the VARICS project last week with a new version I’d been sent, and also making several tweaks to the code and content of the lookup feature. I also changed the language abbreviation ‘Ga’ to ‘Ir’ in the place-names of Armagh content management system and fixed a typo in the Hummell edition on the Burns website that went live before Christmas.
Week Beginning 5th January 2026
My first week back after the Christmas holidays was mostly taken up with travelling to and attending a workshop in Zurich hosted by the ‘Waxing and Waning Words: Lexical Variation and Change in Middle English’ project (https://www.waw-me.uzh.ch/en.html). This project will be producing a Middle English thesaurus comparable to the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) that I was responsible for developing back in 2018, and over the past year or so I’ve been helping out the project’s developer by sharing the BTH code, some sample data, and discussing how it all interoperates.
The workshop was a great opportunity to meet the project team and to work with their developer Tony Harris in person. Working together in person is considerably more effective than communicating by email or even via online video calls and it was hugely productive. We spent at least a day of the day and a half workshop working together and Tony’s knowledge and understanding of the system and its data structures increased massively during this time. We worked with an initial dataset that the project team has created for the semantic domain ‘law’ and by the end of the first day we had created a pathway for importing this data into the thesaurus structure, meaning it could be searched and browsed in the same way as the BTH. We also created links out from the headwords to the Middle English Dictionary. Tony was then able to then apply this workflow to another semantic domain (medicine) and was able to demonstrate a working online resource to the other workshop participants the following day. He should now have everything he needs to process the project’s data an integrate it into the thesaurus as the project proceeds.
It was great to be back in Zurich again, having attended a workshop there some three years previously, but our journey to and from Zurich did not go at all smoothly this time, due to some rather severe weather conditions. There are no direct flights from anywhere in Scotland to Zurich so we had to change flights at Heathrow. Unfortunately due to delays we missed our connecting flights both on the way out (on Tuesday) and the way back (on Thursday), which made for a lengthy and rather stressful journey. This was especially bad on the return journey as our connecting flight was the last flight of the day from Heathrow to Glasgow, meaning we had to stay overnight in London and get an early flight back on Friday morning. This was all pretty exhausting, but we did at least finally get back to Glasgow safely and despite the travel difficulties the workshop was worth it.
I only had time on Monday and Friday afternoon to work as usual this week, and some of Monday was taken up preparing for my trip. However, I did manage to get a few things done. In the run-up to the Christmas holidays I’d been working with the Hansard frequency data and at the start of the holidays I spent some time writing and executing a script to output the data for each year (199 years from 1803 to 2004, with some gaps) as a separate CSV file. I tweaked the data a bit to change the three-character month text to an integer, as this makes it easier to order the data by month (e.g. so ‘apr’ doesn’t come first). It also saves some space. I set the script running overnight and it had completed by the morning. It turns out we only have Commons data and nothing for Lords, with the 199 CSV files taking up 37.6GB (although when zipped this drops to 5GB). I uploaded this to Teams so Marc and Fraser can access it.
On Monday I wrote a further script to export the remaining metadata tables from the Hansard database running on my laptop. These tables contain information about speeches, speakers, parties, roles etc, and are connected through to the frequency data via the speech filename. My scripts exported these tables as CSV files and I added them to Teams too. They should be useful in allowing the frequency data to be limited to a speaker or group of speakers, or a particular political party and such things.
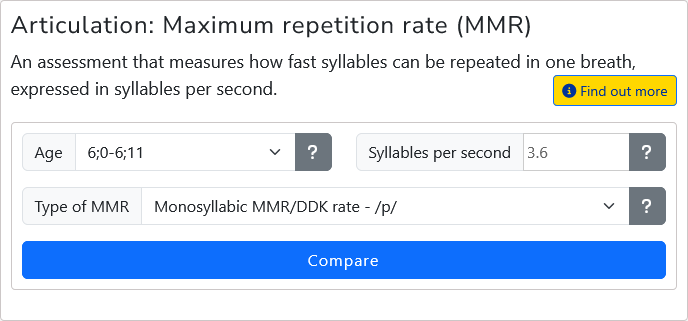
Also on Monday I spent a bit of time working on the VARICS project. Before Christmas I was sent some further data for the lookup feature I’ve developed for the project, this time for maximum repetition rate. It took quite a while to get this working as the new data has a different structure to previous lookup types. Once selected the type then has several subtypes, such as ‘Monosyllabic MMR/DDK rate – /p/’ so I needed to ensure a further selection was added to the interface and also that this was taken into consideration when the data was being queried. The data itself also included several new fields for ‘coefficient of variation’ that also needed to be stored and displayed.
I decided to create a new table to this new data type, populated it with the data from the spreadsheet I’d been sent and created new display and measurement analysis code for the new type. The new display for the speech measure can be seen below:
When I returned to work on Friday afternoon I made some tweaks to the metadata for the Speech Star ‘MRI Modelled Speech Corpus’ (https://www.seeingspeech.ac.uk/speechstar/mri-speech-corpus/) that Eleanor Lawson had asked me to make. I also began to investigate updating the BTH display of lexemes to add in options to order them by date and length of attestation in addition to alphabetically by headword, something we offer through the main Historical Thesaurus and we’d discussed at the workshop. I wrote a script to generate the length of attestation and will hopefully implement the ordering options next week.
I also investigated an issue someone at the workshop spotted with some of the BTH lexemes having start dates later than their end dates. It turns out that there are 197 such lexemes, which I exported as a spreadsheet and sent to Louise Sylvester for checking. Hopefully it’s a simple case of the start and end dates getting accidentally added the wrong way round and a simple switch will sort things.
Week Beginning 15th December 2025
I spent most of Monday and Tuesday this week completing the requirements document for Deven Parker’s Playbills project, which clocks in at almost 5,500 words and covers all of the main aspects of the front-end that will be developed for the project. I’ve sent it to Deven for feedback and we’re going to meet to discuss updates after the Christmas holidays. There are bound to be some aspects that will need changed and I’ll write an updated version after our meeting. After that I’ll begin to implement everything.
Also this week I completed writing the information that Garrick Allen had requested for his proposal, and I made the ‘Urtext Edition of Johann Nepomuk Hummel’s Scottish Songs for George Thomson’ live on the Burns website (see https://burnsc21.glasgow.ac.uk/hummel-edition/).
I also spent some time investigating the code for an app that had been developed for the VARICS project to see whether we might be able to get this hosted through the University of Glasgow’s app store account. Unfortunately I didn’t have much luck. When we’d initially discussed hosting the app I had assumed that it was already published on the App Store and it would be a case of arranging for ownership of the app and its store listing to be transferred to Glasgow, but the app was never actually officially released so this approach won’t work. As the app isn’t available I’ve been unable to even try it out to get an idea of what it is and how it works.
I downloaded the code for the app from GitHub, but I’m not familiar with the Expo framework (https://expo.dev/) that was used to create the app. I followed a tutorial to install the components and get a test app working using the framework, but when I tried to follow the same steps to launch the VARICS app I just get a bunch of errors.
I spent several hours trying to figure out what’s going on but had no success. It may be the case that the code was written a few years ago now and the framework has gone through several updates since then and this is causing issues. However, the real problem is that I have no idea what I’m doing and my attempts to resolve errors are just leading to further errors. Without some guidance from the original app developers I’m not going to be able to make any progress, and we also need to consider whether this is all more trouble than it’s worth. It’s not clear to me what the app will it be used for, and who will use it if we can even get it working. I’ve not been able to get the app working, I’ve not seen any documentation about it or even a screenshot so I know very little about its purpose, but looking at the code it would appear to be an app that allows users to record their speech. It’s unclear to me where these recordings end up and how are they used, and I would imagine that there are considerable ethical and data protection issues that would need to be considered if the app was publicly available, especially as it is aimed at children. I put these concerns to the project team and it looks like they agree that it might not be worth pursuing this, but I’ll learn more in the new year.
Also this week I had a Teams call with the place-names of Armagh project team where I demonstrated the content management system and discussed the project’s data. The session went well, and they raised some interesting questions about how certain aspects of the CMS function. I’ve set up user accounts for the researchers and they’re going to start experimenting with the CMS. I’m also going to think about the structure of their existing data and how this might be migrated into the new system.
I had hoped to spend the rest of my available time this week continuing to work on the place-names of Fife data, but I was only able to spend an hour or two on this, continuing to sort out the place-names elements. The rest of my time was spent looking into the semantically tagged Hansard dataset. I’d worked with this almost ten years ago, but nothing really cam of it. Recently Marc and Fraser have wanted to access it again, and I’d managed to track down the data. I set up a Team in Microsoft Teams where we could all access the data, but the file is not in a usable format. It’s a 10GB tar.gz file containing Base64 encoded lines of text. Years ago I’d managed to extract this and create a database for the data. I had the files for this (taking up around 70GB) on an external hard drive, and it was also set up on an old desktop PC in my office.
When I was on campus on Thursday I attempted to get this PC working, but it only has VGA out and I no longer have a monitor that has a VGA connection. I tried attaching the PC to the projector in the STELLA lab, but was unable to get it working, and the PC made some rather worrying beeps when I tried starting it up. I therefore tried to get the database files running on my laptop, but you can’t just plug 10 year old MySQL data files into the current version of MySQL (as I found out, after trying and temporarily breaking the MySQL instance on my laptop). Instead I downloaded and set up an old version of MySQL and thankfully this worked. But the frequencies table in the database contains 718,424,384 rows and there are no indexes other than the primary key. A query to display the distinct years in the dataset took 22 minutes to execute!
I began the process of indexing the data by year on Thursday evening but it ate up all available disk space on my laptop and then gave an error. On Friday I emptied most of the data from my laptop onto an external hard drive and began the process again. The process took 52 minutes to complete and the index takes up around 17GB, but now a query to return the distinct years is instantaneous, which is pretty promising. The next stage will be to write a script to output the data for each year for each house (commons and lords) into separate CSV files, which will hopefully be more usable. But that’s all for this week, and indeed for this year. If anyone is reading this I wish you a merry Christmas and a happy New Year!
Week Beginning 18th August 2025
I spent a lot of this week working for the Dictionaries of the Scots Language, planning and preparing for some major upcoming changes. Last week I began writing a specification document for a new region / dialect areas interactive map and I completed this on Monday, sending it out to members of the team for feedback and then replying to comments throughout the rest of the week. I then moved on to researching the new XML structure the DSL are using for entries. There have been some major updates to the structure that have been implemented in the DSL’s editing system and will require significant changes to the front-end, the search facilities and the scripts used to process entry XML files after their export from the editing system.
Over the course of the week I wrote a document that detailed all of the changes that will need to be made to the various scripts, databases, indexes and systems to incorporate the changes to the XML structure. I can’t go into too much detail about the new structure or the changes here, other than to say that the structural changes are significant. By Friday I had finished going through all of my systems and the information provided to me regarding the new structure, and had documented all of the updates that would be required. However, during the process a number of questions arose that will need further clarification from the team, and we’ve arranged to meet to discuss things before I begin implementing the updates. Unfortunately due to members of the team being on holiday this likely won’t happen until later in September, but I have plenty of other things to focus on, both for DSL and for other projects, in the meantime.
Also this week I attended online meetings with two researchers who are in the planning stages for new projects. I’d had email conversations with both of them last week, and had arrange online meetings with them this week. The first was with Emanuele Scieri, who works in Theology, and we had a good discussion about his project and the technical aspects it might involve. The second was with Mícheál Ó Mainnín, a place-names scholar at Queen’s University Belfast who is hoping to adapt the place-names system I’ve developed for a new area, and again this was a great meeting and we had some good discussions. I can’t say much more about the projects at this stage, but will need to see how things go.
Other than the above, this week I had an email conversation with Eleanor Lawson about a new project, I made some further tweaks to the VARICS lookup tool, I gave some advice to Robert Davies in the College of Social Sciences regarding interactive maps, and I had an email conversation with Simon Taylor about the updates I’m making to the Place-names of Fife, and I devotes some time on Friday to continuing with the migration of the Fife data to the more standardised structure used by the other place-names resources. I’ve now migrated the main place records, the information about map sheets, classification codes and parishes, although the latter still need parish boundaries to be added. I also began looking at historical forms, but the sources are going to need some significant work, as the source titles and references (e.g. page numbers) are stored in a single field and will need to be split up, which is going to take some processing.
Week Beginning 21st July 2025
Monday was a public holiday this week, which was much appreciated as I’d spent much of the preceding day travelling back from the DH conference in Lisbon. I spent the majority of Tuesday writing my report from the conference, processing my expenses and catching up with emails, which I continued to do throughout the week.
My two main tasks of the week were to add new data to the VARICS lookup feature and the begin the development of an online exhibition for the Robert Fergusson project. The former involved extracting data about speech measurements from a somewhat complicated spreadsheet and updating the data relating to the specific measurements in the online database. I also needed to create new methods for calculating outcomes for some of the new measurements, as previously all calculations were based on the inputted measurement being below 1.5 times the standard deviation whereas some new measurements needed to be above instead, and a further one needed to be within a specified range. I also had to add in some new measurement labels and other information.
For the Robert Fergusson project I’d been given access to a large collection of files that had been used for a physical exhibition about the poet at the Mitchell Library last year, and it’s my job to translate these into an online exhibition. Project RA Amy Wilcockson had arranged the data into folders for each section, with a Word file giving an overview of how each section will fit together, which was all very helpful. It still took a while to familiarise myself with the data, read through the various documents and begin to understand how the information might be presented online. By the end of the week I’d created the overall structure of the exhibition, by which I mean placeholder pages and navigation options for accessing the various pages, and I’d added in the content for the introduction and the first exhibition section, which is about Fergusson’s publications. So far the content is either text or captioned images so it’s not that complicated – more a matter of laying everything out nicely.
One thing I wanted to experiment was a means of animating the content into place as the user scrolls the page, a feature that makes the page seem more alive and interesting. What I didn’t know was how to achieve this, as it’s not something that is easy to search for online. I eventually found a JavaScript library called GSAP (https://gsap.com/) that is a very powerful tool for animating any aspect of a web page. It features a plugin called ScrollTrigger (https://gsap.com/docs/v3/Plugins/ScrollTrigger/) that (as you can probably guess) triggers animations as the user scrolls the page. I spent some time working with the library, but while the tool is obviously very powerful and flexible, I didn’t find the documentation to be all that useful. What I was really hoping for was a series of simple tutorials and demos showing all of the various effects, but the ‘demo’ page for the tool just features a series of more advanced and not especially broadly applicable interfaces rather than things like ‘here’s an example of a block of text swooshing in from the left’. The plugin page itself didn’t feature any working examples and mostly linked to a 20 minute YouTube video, which I personally don’t find as helpful as a text-based tutorial with working examples linked to.
Although I got the tool working and managed to get a couple of experiments set up I felt that my use case (make some blocks of text animate into place as the page is scrolled) wasn’t really covered very well and that I should perhaps look elsewhere. I then found a rather old page (from 2017) that discussed exactly the sort of behaviour I was hoping for (https://css-tricks.com/aos-css-driven-scroll-animation-library/) and found the library that was discussed was still operational (see https://michalsnik.github.io/aos/). This library was really simple and did exactly what I was looking for, so I integrated it with my exhibition pages, making sections animate into place as the user scrolls down the page. Of course I’ll need to see whether the project team likes this feature, but whether we use it or not I feel like I’ve learned something new and hopefully reusable by looking into this.
Also this week I had discussions with the DSL people about how the online site selects headword forms from the XML, and also about some significant changes to their data structures which will have implications for how the files are processed for and displayed on the website. I will need to rewrite my script that processes the XML files to handle the new structure to ensure the new or newly positioned data is extracted as it should be. I may need to update the database structure as well, in order to store things like the regional information, and it’s possible the Solr index structure may also need to be updated. The XSLT file that transforms the XML files into HTML whenever an entry is loaded will also need to be rewritten to deal with the new structure. So there will be a lot to do in the coming months!
I also fixed an editing error that had occurred with the Thesaurus of Old English and had an email discussion with Tony Harris about the Bilingual Thesaurus code I’d previously sent him for use on a new project, and how I process data and develop user interfaces. It looks like we’ll be meeting up in Zurich in January, which will be useful.
Week Beginning 21st April 2025
It was another four-day week due to Easter Monday, and I spent a fair amount of my time working for Speak For Yersel. For our abstract for DH2025, I received some new, high-resolution images of the graphs from co-author Marc Barnard and after a little more tweaking and dealing with the submission process I was able to complete the submission process. I still need to actually sign up for the conference, though, which is something I’m hoping to be able to do next week.
One of the reviewers of our abstract had made a comment about user fatigue and enquired about how many users actually completed the surveys and this prompted me to undertake some investigation. I created a series of database queries that for each user extracted counts of the number of submitted answers in the morphology, lexis and phonology surveys. I then exported the data into Excel spreadsheets, one per region (Scotland, Northern Ireland, Ireland and Wales) and sent this data on to Jennifer in case it was of some use.
However, I did have to point out that the counts for each user are of answers submitted and some questions allow for multiple answers to be selected so there’s not an exact 1:1 relationship between the figures and the number of questions. Also, a user can complete a questionnaire more than once (or quit mid-way and then begin a second time). I noticed that there were a few users who have submitted many more answers than there are questions. For example, in the NI data there is a user who has submitted 102 morphology, 105 lexis and 76 phonology answers, even though there are only 34, 35 and 29 questions respectively. It’s not possible to ascertain exactly what prompted the user to submit so many answers, but it is perhaps a case of someone passing an iPad round a group of people.
I then decided to experiment with visualising the data, and for this I used the Highcharts library (https://www.highcharts.com/). There are lots of interesting visualisation that can be made with the data, and my first attempt was to generate a stacked column chart (https://www.highcharts.com/demo/highcharts/column-stacked). I decided that it would be useful to visualise all of the answers submitted by each user over time so wanted to plot each user as a column, with columns on the x-axis arranged chronologically by date of user account creation. Each column would then be split into three coloured sections showing the number of answers submitted across the three surveys (morphology, lexis and phonology).
I wrote a little script to generate the JSON data that Highcharts can easily work with, and adapted the Highcharts example linked to above to work with the new data on my local PC. The resulting graphs include a lot of columns (6379 for Scotland, 785 for Northern Ireland, 350 for Ireland and 1487 for Wales) and everything does get rather squashed together and some gaps can get lost, but what is interesting is how these graphs show the overall pattern of submissions. On the whole most users across all regions made a decent stab at completing all surveys, as there are clear bands of colours, admittedly with some variation and gaps. The graphs also show the outliers, especially the people who submitted many more answers than there are questions. One user in Scotland in particular seems to have gone a bit crazy, and this then causes the rest of the graph to be rather squashed.
Here’s the graph for Northern Ireland, showing a few users who submitted many more answers than there are questions, a few users who submitted very little, and an overall pattern showing users making a decent stab at completing all three surveys.
The pattern for Ireland is broadly similar, and with less users it’s easier to view the individual columns:
Wales has considerably more users, which means individual columns can get lost, but it’s still possible to get an overall sense of user completion rates:
For Scotland we have an awful lot more users, plus as mentioned earlier one user who submitted huge numbers of answers, which results in a graph that squashes up all of the other data:
I had to regenerate the Scotland data and graph as after my first attempt I realised that the Scotland resource features more than just the surveys but also features follow-on questions, quizzes and other activities and I hadn’t filtered all of this out. I was also interested to expand the x-axis to allow a more nuanced view of the data, and also to place a maximum extent on the y-axis to avoid one user affecting the display of data for all other users:
The resulting graph above (which you’ll need to open to view properly) demonstrates a lot more variation in user submissions that are lost from the smaller graph and demonstrates how the smaller graph with its big blocks of solid submissions doesn’t reflect reality. Having said that, the overall picture still shows a decent number of users submitting a complete or near-complete set of answers. Of course there is still much that could be done with the data. Even using the same stacked column graph, rearranging the users by number of submissions would be interested, and may demonstrate how the overall picture when presented in date order could possibly obscure the number of users who didn’t submit much data. But that’s for another time.
Also this week I made a few changes to the Speech STAR resource including adding a link to the ‘in clinic’ site form the top level tabs for Seeing Speech, Dynamic Dialects and the STAR site, as you can see here: https://www.seeingspeech.ac.uk/speechstar/. I also had a chat with Eleanor about the visibility of the STAR sites in search results.
I also made a few further updates to the VARICS lookup test that’s still in development, including updating the ‘how to’ guides and linking to them from the longer textual descriptions of measurements.
On Friday I had a Teams meeting with Katie, Matt and Kitt from the Books and Borrowing project to discuss the new versioning system I’m going to develop. We agreed that I will develop the full versioning system I specified in the document I sent around two weeks ago, and I’ll aim to get started on this in the next week or two.
Week Beginning 31st March 2025
My main task for this week was to complete my work on the new API for the Historical Thesaurus. As I mentioned last week, I’ve been working on a new version of the HT website that fully separates out all data queries into a single API, which the front-end then connects to in order to pull in the necessary data. The current version of the website was developed over many years and data queries were found all over the place – embedded in the front-end scripts and located in AJAX calls, with an additional, initial stab at an API used for the lexical sparklines. Over time it all became something of a tangled mess.
The new API brings all data queries together in one place, offering options to access the data as either JSON or CSV files. This is a much neater solution that is easier to maintain. It also makes updating (or in future entirely replacing) the front-end much simpler as it no longer includes database calls and only needs to include minimal data processing.
The API endpoints I’ve created cover every data query that is required to power the front-end, and they feature descriptions, a list of the arguments that can be passed to them and examples. As mentioned previously, the data can be accessed as JSON (used by the front-end) or CSV. It’s possible that the structure of the CSV files could be improved – it’s difficult to represent multi-dimensional data in a two-dimensional spreadsheet – so depending on feedback from Marc and Fraser I might need to do some further work on this aspect.
In addition to developing the API I also created a new version of the front-end that connects to it. In terms of visuals and functionality this is identical to the live site, but every script has been updated to funnel all data queries to the new API. I’ve tested it out pretty extensively and all seems to be working perfectly, so that’s my redevelopment of the back end of the Historical Thesaurus website completed. I just need Marc and Fraser to test out my test site, and once I have their approval I’ll replace the live site with the new version.
Also on my long-term ‘to-do’ list is redeveloping the front-end to migrate the interface to Bootstrap, as I did for the Bilingual Thesaurus (https://thesaurus.ac.uk/bth). This will be a pretty major undertaking, as many of the features of the current site (e.g. the timeline popup) use the jQuery UI framework and this would all need to be replaced with Bootstrap equivalents. My plan at this stage will be to replicate the current HT interface in Bootstrap, but we might want to consider a larger overhaul of the interface. Either way it will likely be a while before I am able to devote any time to this.
This week I also published the new ‘cognate reference’ search facility that I’d created for the Anglo-Norman Dictionary, which you can find in the corresponding tab found on the search page: https://anglo-norman.net/search/. This allows you to search for forms found in the cognate dictionaries, so for example finding all AND entries that reference OED words ending in ‘ment’: https://anglo-norman.net/search/cogref/*ment/OED. All seems to be working perfectly and hopefully this will be a useful addition to the website.
Also this week I made some minor but hopefully very helpful tweaks to the interface for the DSL website on our test server, ahead of the launch of the new data which is scheduled to take place the week after next. I updated the page width on narrow screens so that the pages are now wider throughout the site, meaning there is less wasted space down either side of the page. I also updated the site buttons to make them inline-block rather than inline, with a 5px margin at the bottom. This means buttons don’t get split over multiple lines and don’t overlap when there are multiple lines of buttons on narrow screens. I also took the opportunity to update the ‘fixed’ header that appears as you scroll down the entry page. This now takes up with whole width of the browser (at all screen dimensions), which gives more space and looks better. These updates are currently only available on our test version of the site, but will go live along with the major update when it happens in a couple of weeks.
I also had a chat with the Books and Borrowing people about new data that is to be added to the resource. It’s not going to be as simple as just allowing researchers to add new data to the CMS, as Katie and Matt want to add a versioning system to the data in order to ensure that it’s possible to search and reference only the data that was published during the course of the project, as well as searching and referencing all data including subsequent updates. This is going to need some careful consideration as it will likely require changes to the database, the CMS, the API, the Solr indexes and the front-end, and of involvement with the project officially ended several months ago.
Finally this week I made some further updates to the new ‘lookup’ feature I’ve developed for the VARICS project. I updated the lookup page to replace the short definitions with new ones that had bene sent to me, and to remove the measures that the team no longer require. I also added a yellow ‘Find out more’ button to the short description that appears above the form when you press on a measure. Pressing on this takes you to the relevant longer definition. This currently opens in a new tab so the user doesn’t lose the form. I then added the longer definitions to a WordPress page I created, with each definition appearing in a box that has a hidden ID, ensuring that when the ‘find out more’ button is pressed the relevant section of the page loads. I also created a WordPress page for the ‘How to’ information that I’d been sent, which features text and infographics for each ‘how to’, again with each one in a separate box. I made the images appear as links that when pressed on load the full-size versions, as some of the text can be somewhat indistinct in the in-page version.
I’ll be on holiday for most of next week, but will still be working for some of the week and there will be an update as normal after that.
Week Beginning 10th March 2025
I spent most of this week continuing to implement the new cognate reference search facility for the Anglo-Norman Dictionary. When I left off last week I was midway through implementing a script to generate search form variants for all of the cognate reference forms found in the dictionary entries. These are the words found in the grey box towards the top of an entry page such as https://anglo-norman.net/entry/asseger. My script splits up multiple forms and bracketed sub-headwords, where brackets are found within a form the script generates variants with and without the bracketed text, multi-word forms have each word stored separately (in addition to the full string) to enable each word to be searched for, and where a dash is used variants are generated with the dash, with a space in place of the dash and with no space at all.
After fully testing the script and its output I then needed to work on the scripts that update dictionary entries to ensure that they also generate or regenerate the cogref search forms whenever they execute. This included the batch upload process I use when handling large-scale updates to the database and the entry publication script found in the dictionary’s content management system, as used by the editorial team when updating individual entries. I worked with the editor Geert to test out these updates and with a bit of tweaking I got everything working.
I then updated the ‘View entry’ page in the dictionary’s content management system so that all of the cogref search terms are displayed, so the team can check what can be searched for. As mentioned previously, cogrefs are split into individual search terms on the space character, allowing individual words to be searched and this does mean that parts of speech and numerals also get stored as individual search terms, but I don’t think this will be a problem – no-one will see these search terms, only the listed ‘Display form’ will be shown in the results and the ‘search forms’ just show the variants that are stored behind the scenes. I did consider stripping out all numerals and parts of speech but there are just so many possible permutations that it would be very tricky to catch them all, and storing them is not a big issue. So for example for the entry ‘asseger’ linked to above, the following forms are generated:
Where there are multiple forms (e.g. Gdf) these are stored as separate search forms. Where there are subheadwords (e.g. DEAF) these are similarly split into separate search forms. Where there are forms with spaces (e.g. OED) the full string is saved as a search form, but so too are each individual word. Where there are brackets within a word (e.g. MED) then forms are generated both with and without the bracketed text. This also works where there’s only an open bracket, as happens quite often with MED headwords. There were also a handful of MED cogref forms that had multiple brackets (around 13, I think). In such cases the generated forms only include versions with all of the bracketed text and none of the bracketed text, as the generated forms for the entry ‘Oxherd’ demonstrate:
He above also demonstrates the variants that are created when a dash is used, and any forms with slashes are treated in the same way.
With all of the cogref search data in place and facilities established to ensure the data will be updated when entries are edited I then moved onto the creation of the new search facility itself. The first step was to create a new endpoint in the API through which the search requests will be processed. It took a while to implement and test this, ensuring that wildcards can be used in the search and enabling the search to be limited to one or more cognate dictionaries. The search results initially brought back rows for each cogref form, so if (for example) the search was for ‘siege’ as found in the above screenshot there would be three individual DEAF search results, each with information about the associated entry. However, what the search needed to return was entries and then within each entry a further section listing the individual search results and I therefore needed to switch things around slightly.
With the API updated and the new search endpoint working I then needed to update the front-end to add the new search form to the advanced search page, connect the form to the API and ensure that any returned results were processed in the same way as the other advanced search options (for example with pagination, links to entries and a way to return to the form with previously entered options remembered). I created all of this in a test version of the page so the editors and I could test things out without making the update publicly available.
The new Cogref search appears as a new tab in the Advanced Search after ‘Languages’. It consists of some introductory text, a search box where a cognate form can be entered (with or without wildcards), and a section where the cognate dictionaries you want to search can be selected. These appear as checkboxes which are all checked by default. There’s an ‘All’ checkbox that allows you to select / deselect all of the other checkboxes, so to limit your search to just DEAF, for example, press ‘All’ to deselect everything then press ‘DEAF’. The cognate dictionaries have tooltips that display the full names, as the following screenshot demonstrates:
As with the headword search, by default any text you enter into the ‘Cognate Form’ box matches any corresponding string in the search forms – so for example ‘noble’ is actually treated as ‘*noble*’. To perform an exact search use double quotes. As previously mentioned, search forms have been created for many different variants and where a form has multiple words or is split with dashes each individual word is treated as a separate search form. So, for example, if you perform an exact search for “herd” you will find things like ‘nout-herd’, ‘shep-herd’ etc.
The search results display details of what you’ve searched for, the entries that feature a cogref form that matches and the specific cogrefs that feature a form that matches your search criteria, as the following screenshot demonstrates:
The editors are now testing out the new search and hopefully we’ll be able to go live with it in the next week or so.
Also for the AND this week, the editor Karen spotted an issue with the cross references between entries, which are generated whenever an entry is updated. Some cross references weren’t being found and it turns out that this was because the homonym number is separated from the lemma with a hash in the XML, but with an underscore in the ‘slug’ used in the website (this is correct and how things should be). What this meant was that the cross reference generator was taking the slug (e.g. Partein_1) and looking for that in the XML files and obviously not finding any matches as it’s recorded as ‘Partein#1’ in the XML. I therefore updated the code so that the xref search turns ‘_’ into ‘#’ and the xrefs are now being found and generated.
This week I also did a bit of work for the VARICS project, adding in a new batch of short descriptions for measurements in the lookup feature I’m developing and discussing the ancillary text with members of the project team. I also had a chat with Jennifer Smith about our Speak For Yersel paper for DH2025 and gave some feedback to Matthew Creasy about his Mallarmé Chancellor’s Fund application, which he submitted on Friday.
I also responded to a Query from William Ashford of the DSL about Google Analytics, mobile versus desktop users and search engine optimisation and responded to a query from Ann Ferguson regarding a couple of issues relating to the bibliography search.
Week Beginning 10th February 2025
I divided my time between many different projects this week. For the Anglo-Norman Dictionary I made a few further tweaks to the new cognate references section that we went live with last week, and I also received a new batch of several hundred new or reworked entries that are to be added to the dictionary, which I’ll process next week. For the Dictionaries of the Scots Language I had an email conversation with editor Ann Ferguson about the structure of URLs and also gave some consideration to the bibliography search, based on feedback I received towards the end of the week. I’ll continue to work on this next week.
I also found a bit of time this week to begin work on a new version of the Historical Thesaurus website. The current website’s backend is a bit of a mess, as it was cobbled together over many years as new features were added. What I’ve been meaning to do for a while now was to rework this in order to extract all data querying and processing code from the front-end, separate it out and develop a single, unified API for the site, an approach I’ve taken with all of the large projects I’ve been involved with for many years now. This is going to be a rather large task, but I made a start this week: I set up a new version of the website and began the process of creating the API. So far I’ve only got the ‘random category’ feature on the homepage working with the new API, but I’ll continue working away at this as time allows until it’s all done. There won’t be any change to the front-end (although I’m also separately considering a Bootstrap-based refresh of the interface), but the update will leave the data querying side of things in much better shape for the future.
For the VARICS project I continued to work on the new look-up feature. Following last week’s traffic light experiments the team requested a more simple approach for the traffic lights, so I created new images featuring a subtle gradient and a white border, as you can see below:
I also added in a new ‘Try again’ button that would reload the form, which was subsequently renamed ‘Start again’. The team prefer this simpler approach so it looks like this is what we’ll be going with. I now need to wait until further data is sent to me before I continue to develop the feature.
For the place-names projects, I spent some time investigating an issue with the advanced search in the new map interface. An element language search was not working unless a specific element was also selected. For example, a search for all place-names containing Old English elements wouldn’t run, but selecting Old English and then selecting the element ‘tūn (OE)’ worked perfectly. It took a while to track down the issue, but thankfully once identified fixing it was trivial: there was a typo in the code for the API. The system was already set up to allow a search for element language without specifying an element, but in such circumstances the code failed to run because of the typo. I’ve fixed this now on all of the place-names sites. I also fixed a strange issue with the advanced search pop-up disappearing when parishes towards the end of the list were selected. This issue was only occurring in Chrome and not in Firefox (my default browser) and an update to the stylesheet for the map pop-up thankfully fixed the issue.
I also participated in an online meeting with the Iona project team on Wednesday this week where we discussed some of the map-related issues that had been brought up at the advisory board meeting and how (or if) we should address these. I ended up with a list of updates that I’ll need to make to the interface, another thing I’m hoping to tackle next week.
Also this week I had a brief in-person meeting with Joanna Kopaczyk and her project RA Pia Lehecka to discuss Joanna’s new DOST digitisation project. It was good to meet the other members of the team and I’m looking forward to working for the project over the next few months.
I also met with Alan Riach in Scottish Literature this week. Jean Anderson had contacted me last week to put me in touch with Alan, who was wanting some help to publish some old radio broadcasts that were previously available on one of our old servers that has since been decommissioned. Alan managed to find some audio CDs containing the recordings and I met with him to collect them, together with some additional recordings and a few DVDs. I spent some time towards the end of the week extracting the audio and video data from this media and creating a simple website where the files and accompanying transcripts will be accessible to students. I haven’t quite finished this task yet, but should have an initial version completed early next week. The resource will be password protected and only available to students and staff, as there may be licensing issues relating to the recordings – for example relating to incidental music used during the recordings.