Category: STAR
Week Beginning 3rd August 2026
I worked a total of four days over the past two weeks, and was on holiday for the remainder. During this time I had a meeting to further discuss a place-names related AHRC proposal I’m involved with. I can’t really say much more about it at this stage, but the proposal is coming together. I also had to spend some time working with IT Support and Luca to figure out why our local server kept going offline repeatedly. It looks like this was caused by the server getting swamped by requests from one particular source (almost certainly bot or AI) and thankfully IT Support were able to block this, after which the server was stable again. It’s something we’re going to have to keep looking out for in future. I also spent a bit of time working with Luca to get automatic WordPress updates working on our local server, as the way sites had been set up meant that the setting was not working. Luca managed to find a solution to this, which is really great.
I also spent a bit more time working on the Burns Supper Map, creating a record for it on this site (see https://digital-humanities.glasgow.ac.uk/project/?id=156), adding more suppers that had been submitted via the survey and making some requested edits to existing suppers. I also set up access to Google Analytics for the other two members of the project team.
In addition, I investigated an issue with the Scots Syntax Atlas after someone suggested that the linguists’ atlas was looking somewhat blurry. I managed to figure out why this might be the case, although I’m not entirely sure whether this is a new issue or if the markers always looked like that. I contacted the project PI and suggested a couple of updates, but I haven’t heard back yet so will need to wait and see what she says.
I spent most of the remainder of my time working on updates to our new test interface for Dictionaries of the Scots Language and working through the list of outstanding items for the DOST Auld Laws project. For the DSL I completed the updates to the bibliography page that I began working on a couple of weeks ago. I implemented pagination of the entries associated with bibliographical items, with navigation bars appearing above and below the entries, with 20 appearing per page and ‘jump to page’ buttons also appearing, just like with the search results. This works pretty well, but is somewhat cumbersome for someone like Sir Walter Scott, who is referenced in 2861 entries, split over 144 pages. We don’t have this issue with the search results are these are capped at 500 (25 pages) so we might need to think of other ways of handling this.
I also ensured that headword searches that don’t yield any results automatically perform a fulltext search for the term supplied. This works on the live site, but only when both dictionaries are selected. With the new site there are separate quick searches for SND and DOST so the additional search wasn’t being triggered. It is now, as is the advanced headword search for both dictionaries.
I also made tweaks to the DSL’s new regional map based on feedback I’d received – adding in some content where we previously had placeholder text and ensuring the ‘About’ popup didn’t disappear off the bottom of smaller screens and a few other small updates. I then began to look at the ancillary pages and how we can make them look a bit nicer. I spent a bit of time on the ‘Word of the Week’ page and liaised with William Ashford, who is responsible for such content about this, and further updates that were going to make to the ancillary content closer to the launch date of the new site (which will hopefully be in November).
For the DOST Auld Laws project I added the top navigation bar that will link the site in with the SCOTS Corpus and CMSW. I added in copyright information and added facilities to download page images and the XML files for each document. These being up a pop-up asking for users to abide by the license before leading to the actual content, which hopefully won’t be too annoying. I also added in the ‘cite’ popup to all document pages, which took a little time to implement, and added in Google Analytics. I also made the image thumbnails on the document overview pages smaller and placed them in a collapsible section that is closed by default, plus I removed the introduction to the documents page, as this will be covered by the homepage.
I also removed some pages that didn’t have content (e.g. blank pages) from the beginning and end of some of the documents and I added a feature to turn off and on the line highlighting feature. The highlighting feature allows the user to click on a line of text in the image or text for a page and for that line to be highlighted in both the image and the text, which is pretty nice. Unfortunately the line highlighting gets in the way of the image viewer’s zoom and pan functionality on touchscreens, making it a somewhat unreliable and frustrating experience. This new feature removes the option to ‘click’ on a line, meaning pointer events are not intercepted and make their way reliably through to the image viewer, which works much more smoothly.
Also this week I had an email conversation about user feedback and walkthough videos for the STAR resources and booked my accommodation for the DHC conference in Sheffield. Next week I’m back in Glasgow and back working a full week, with summer holidays all over.
Week Beginning 19th January 2026
I worked on many different projects this week, but the one I spent the most time on was the Dictionaries of the Scots Language. I’ve not done much work for the DSL since the intensive period I spent developing the new website interface and deploying it on our test server ahead of the face-to-face meeting in mid-November. I had a list of further updates I needed to make following on from this meeting, but I needed to work on other projects since then and hadn’t got around to it. I’d also received a number of emails about changes to the presentation of entries reflecting the structural changes to the entry XML that I’d put to one side.
On Wednesday I had an online call scheduled with the DSL team to discuss the new front-end and it seemed like a good opportunity to get back to grips with all of my outstanding DSL tasks. This mainly involved making updates to the XSLT on our test server to tweak the layout of various items in the new entry XML structure, such as adding commas between tags when they are rendered, ensuring certain tags or attributes that weren’t getting rendered before appeared in the generated HTML, updating the styles of certain elements like the content warning labels, fixing a few bugs such as the ‘sticky’ heading not displaying in certain circumstances. There were at least 20 such items that needed investigating, fixing and testing, so this took quite some time to work through, but I managed to complete it all during the course of the week.
The meeting itself was very useful and as always it was good to catch up with some of the other DSL team members. There’s going to be a big push towards getting the new website interface ready for publication this year, and I’m obviously going to be involved in this process. I already have a number of items I need to sort out with the new interface and I’ll try and get started on these over the coming weeks.
I also spent a bit of time this week working for the Anglo-Norman Dictionary, investigating a strange occurrence with the publication of updates to entries, which turned out to be a user rather than a system issue, reinstating the links out from entries to the DMF dictionary, as their website is now properly back online again, and tweaking the wording of the quick search and ‘jump to entry’ text throughout the site.
I also did small amounts of work for several other projects, such as updating the licensing statements across the Seeing Speech and Star sites, fixing an issue with the ‘download song’ facilities on the Editing Robert Burns site, sorting an issue with the HiMuJe Malabar site, submitting my expenses from the Zurich workshop, exporting some SCOSYA data for Jennifer Smith, helping to sort out an issue with the Helsinki Corpus, and having a conversation with Clara Cohen about a new proposal she’s putting together. I also made some further updates to the VARICS look-up system, adding in some introductory text, some further references, and reworking the measurement processing so that when a red or amber result is given new textual sections about what this means and what the next steps should be appear underneath in collapsible accordion sections.
Also this week I had a meeting with the Burns Supper Map team to discuss the data that is now coming in and how and when I should start working on a new interactive map to visualise it. I also put in a request for a new subdomain for the project that was set up by the end of the week. Next week I’ll probably write a brief specification document for the front-end.
My final project of the week was the Place-names of Armagh project, for which I started working with some existing place-name data for the area. There are around 230 place-names and several thousand historical forms and I spent quite some time researching how the data was structured and how it might be mapped onto the Glasgow place-names system. This included analysing the geospatial data, including shapefiles for Townlands and what I though was Parishes (but actually turned out to be the same as for Townlands). I had hoped to be able to import the data by the end of the week, but my analysis of the data raised a lot of questions that still need to be addressed, and I’ll need to continue with this next week.
Week Beginning 5th January 2026
My first week back after the Christmas holidays was mostly taken up with travelling to and attending a workshop in Zurich hosted by the ‘Waxing and Waning Words: Lexical Variation and Change in Middle English’ project (https://www.waw-me.uzh.ch/en.html). This project will be producing a Middle English thesaurus comparable to the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) that I was responsible for developing back in 2018, and over the past year or so I’ve been helping out the project’s developer by sharing the BTH code, some sample data, and discussing how it all interoperates.
The workshop was a great opportunity to meet the project team and to work with their developer Tony Harris in person. Working together in person is considerably more effective than communicating by email or even via online video calls and it was hugely productive. We spent at least a day of the day and a half workshop working together and Tony’s knowledge and understanding of the system and its data structures increased massively during this time. We worked with an initial dataset that the project team has created for the semantic domain ‘law’ and by the end of the first day we had created a pathway for importing this data into the thesaurus structure, meaning it could be searched and browsed in the same way as the BTH. We also created links out from the headwords to the Middle English Dictionary. Tony was then able to then apply this workflow to another semantic domain (medicine) and was able to demonstrate a working online resource to the other workshop participants the following day. He should now have everything he needs to process the project’s data an integrate it into the thesaurus as the project proceeds.
It was great to be back in Zurich again, having attended a workshop there some three years previously, but our journey to and from Zurich did not go at all smoothly this time, due to some rather severe weather conditions. There are no direct flights from anywhere in Scotland to Zurich so we had to change flights at Heathrow. Unfortunately due to delays we missed our connecting flights both on the way out (on Tuesday) and the way back (on Thursday), which made for a lengthy and rather stressful journey. This was especially bad on the return journey as our connecting flight was the last flight of the day from Heathrow to Glasgow, meaning we had to stay overnight in London and get an early flight back on Friday morning. This was all pretty exhausting, but we did at least finally get back to Glasgow safely and despite the travel difficulties the workshop was worth it.
I only had time on Monday and Friday afternoon to work as usual this week, and some of Monday was taken up preparing for my trip. However, I did manage to get a few things done. In the run-up to the Christmas holidays I’d been working with the Hansard frequency data and at the start of the holidays I spent some time writing and executing a script to output the data for each year (199 years from 1803 to 2004, with some gaps) as a separate CSV file. I tweaked the data a bit to change the three-character month text to an integer, as this makes it easier to order the data by month (e.g. so ‘apr’ doesn’t come first). It also saves some space. I set the script running overnight and it had completed by the morning. It turns out we only have Commons data and nothing for Lords, with the 199 CSV files taking up 37.6GB (although when zipped this drops to 5GB). I uploaded this to Teams so Marc and Fraser can access it.
On Monday I wrote a further script to export the remaining metadata tables from the Hansard database running on my laptop. These tables contain information about speeches, speakers, parties, roles etc, and are connected through to the frequency data via the speech filename. My scripts exported these tables as CSV files and I added them to Teams too. They should be useful in allowing the frequency data to be limited to a speaker or group of speakers, or a particular political party and such things.
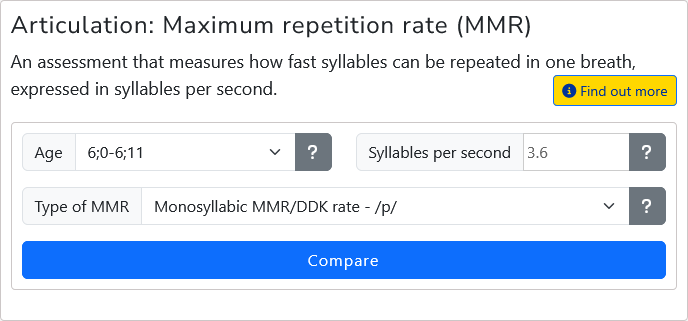
Also on Monday I spent a bit of time working on the VARICS project. Before Christmas I was sent some further data for the lookup feature I’ve developed for the project, this time for maximum repetition rate. It took quite a while to get this working as the new data has a different structure to previous lookup types. Once selected the type then has several subtypes, such as ‘Monosyllabic MMR/DDK rate – /p/’ so I needed to ensure a further selection was added to the interface and also that this was taken into consideration when the data was being queried. The data itself also included several new fields for ‘coefficient of variation’ that also needed to be stored and displayed.
I decided to create a new table to this new data type, populated it with the data from the spreadsheet I’d been sent and created new display and measurement analysis code for the new type. The new display for the speech measure can be seen below:
When I returned to work on Friday afternoon I made some tweaks to the metadata for the Speech Star ‘MRI Modelled Speech Corpus’ (https://www.seeingspeech.ac.uk/speechstar/mri-speech-corpus/) that Eleanor Lawson had asked me to make. I also began to investigate updating the BTH display of lexemes to add in options to order them by date and length of attestation in addition to alphabetically by headword, something we offer through the main Historical Thesaurus and we’d discussed at the workshop. I wrote a script to generate the length of attestation and will hopefully implement the ordering options next week.
I also investigated an issue someone at the workshop spotted with some of the BTH lexemes having start dates later than their end dates. It turns out that there are 197 such lexemes, which I exported as a spreadsheet and sent to Louise Sylvester for checking. Hopefully it’s a simple case of the start and end dates getting accidentally added the wrong way round and a simple switch will sort things.
Week Beginning 3rd November 2025
I spent pretty much the entirety of this week continuing to develop the new interface for the Dictionaries of the Scots Language website, applying the Bootstrap-based mock-up I’d created many months ago to an instance of the actual DSL website running on my laptop. I can’t really go into too much detail about the new interface or provide any screenshots at this stage, but it’s been a pretty intensive process as every aspect of the old interface needs to be changed and various parts of it need to be integrated with WordPress, for example making widgets and ensuring the new layout works with different templates.
I managed to complete the bulk of the work this week (although this did include working several hours over the weekend too), in preparation for next week’s face-to-face DSL team meeting. This included the search results pages, the advanced search page, the dictionary entry page and the bibliography page. This may not seem like a very long list, but there was a huge amount of work to do on each of these pages, such as implementing the site panel for the entry page that features the dictionary browser, the search results browser and a new ‘entry log’ that keeps a record of entries the user has looked at during their session. I reckon the new interface is looks really good, and is a massive improvement on the live site, although there will inevitably be many further changes to be made before anything goes live.
I still need to complete the new top-level ‘About’ page, which acts as a large menu page, plus ensure that all regular WordPress pages work with the new interface and include the quick search. I’m hoping to finish these things off and then apply the interface to our online test instance of the site ahead of Wednesday’s meeting next week.
Also this week I spent a bit more time preparing for a talk about Speak For Yersel and Jennifer Smith and I were scheduled to give at the University of Edinburgh the week after next. However, later in the week we heard from the organisers that the University will be on strike when our talk is scheduled and we therefore reached a decision to cancel. It’s possible that we’ll be able to reschedule, as we are not directly involved in the strike action, but we’ll just need to see.
Also this week I created an initial version of a website for Henry Ivry’s project and contacted researcher Jenny Buckley with some further information about the processing of historical newspapers that might be of use for her project. I also made a small update to the Speech Star resource and had an email conversation with Eleanor Lawson about access restrictions for the resources data.
I participated in an online meeting regarding sharing the SCOSYA data with the Mozilla Foundation this week, and I also had a meeting with Pauline Mackay and Cleo O’Callaghan Yeoman to discuss a new phase for the Interactive Map of Burns Suppers. I subsequently spent a bit of time reviewing some materials for the site. Finally, I exported some data from the Historical Thesaurus that we’re going to share with another project.
Week Beginning 1st September 2025
I spent the majority of this week working on the new, interactive region and dialect area map for the Dictionaries of the Scots Language. DSL editor Vasilis had created a prototype interface and geoJSON data before the summer and a few weeks ago I had a meeting with a few members of the DSL team about creating an new version of this that would be more suited to the DSL website and would be optimised for mobile use. I then created a specification document which I shared with the group and after some feedback we reached agreement on what needed to be developed.
I was able to base the new interface on my previous map-based projects such as the place-name resources and the Scots Syntax Atlas, and as with these I decided to use the Leaflet.js mapping library. My first task was to incorporate all of the geoJSON data into an interactive map to get an idea of how it might work and whether there would be too many areas for people to make sense of. The first issue I encountered was that the geoJSON data had been created using a projection that Leaflet did not support. I’m not exactly a GIS expert, but apparently Leaflet expects all coordinates to be latitude and longitude using the Coordinate Reference System (CRS) WGS84. The DSL regions geoJSON data stored its coordinates as EPSG 3857, so the coordinates were things like ‘[ -203142.297936542046955, 7877431.976650067605078 ]’ rather than ‘[-1.804316665436796,57.55628903006679]’. This meant that no data was getting displayed on the map. Thankfully I’d encountered this issue before whilst working on the Speak For Yersel project, and I was able to use QGIS to convert the data into the alternative CRS, after which it appeared on the map correctly.
The next issue was that the geoJSON was around 11MB in size, which is far too big for downloading into a webpage. Again, we’d dealt with this issue with Speak For Yersel, where we’d used an algorithm to simplify the polygons and massively reduce the file size. Unfortunately this was a task that another member of the team had performed and going through my blogs and emails I was unable to find details of exactly how this had been accomplished. I tried a couple of approaches in QGIS but they converted the polygons to really basic shapes that were totally unsuitable. Thankfully I found a really amazing resource called mapshaper (https://mapshaper.org/) that allows you to paste in a geoJSON file, visualise it and adapt it, including simplifying it. After some experimentation I exported a file that was just over 1MB in size, which was much more suitable whilst retaining sufficient detail.
I was then able to plug this data into a Leaflet map and visualise it. As agreed with the team, we would have separate maps for regions and dialect areas, so I updated my code to only display regions, stripping out the dialect areas. Initially I created an interface based on the Speak For Yersel maps, with polygons appearing with a faint grey dotted border and the ability to hover over a region, which would highlight it with a yellow border and display the region’s name in a box in the top-right of the screen. I realised that this approach was not going to work very well, firstly because hover-over doesn’t work very well on touchscreens and secondly because there are generally multiple layers present at any one point of the map and highlighting these and displaying all of their names as the cursor moves around the map would be messy.
Instead I decided to remove the hover-over and focus on the click event. We’d decided that when the user clicks a point on the map all regions represented at this point would be highlighted on the map, and information about them, plus the dialect areas would appear in a pane in the map, with options to turns on and off each layer.
In order to grab details about each layer that was represented at the point the user clicked on I needed to use a Leaflet plugin called ‘Leaflet point in polygon’ (https://github.com/mapbox/leaflet-pip). Using this gave my code access to as handy array of all of the layers found at the point where the user clicks, thus allowing me to highlight them on the map and access their details to present them in the information pane.
While Vasilis’ prototype had used solid blocks on the map to represent the regions, we’d decided instead to make these transparent so people could still make out the placenames and features of the underlying map. I also decided to replace the dotted lines with solid ones, as these looked a little neater where multiple polygons converged. I had been worried that there would be too much data and that the map would be too cluttered to be understandable, but I think the map works with all regions visible, and it helps give people a sense of which area might be interesting to click on.
I worked on the information pane, creating lists of regions and dialect areas found at the point clicked on and making it possible to turn these on or off, using a red border and transparent background for regions and a purple border and background for dialect areas, with dialect areas switched off by default. I also decided to add a map marker to where the user clicked to make it clearer how the highlighting has been calculated. I also added in the option to close the information pane (which would also remove all highlighting). This can also be achieved by pressing anywhere on the map that isn’t a region (e.g. in the sea). The screenshot below shows a section of the map with all regions located at the point clicked on highlighted in red and one dialect area (Northeastern Scots (a)) selected and shown in purple:
This is quite a lot of information, but note that the purple area is not visible by default and has to be manually selected. Also, using the options in the information pane you can very easily filter out any layers you’re not interested in. The following screenshot only has one layer (Moray Firth Fishing Villages) highlighted, for example:
There’s still work to be done with the information pane – for example the listed regions and dialect areas should ideally be hierarchically ordered, but I’m pretty happy with how things are developing so far.
I then decided to switch my focus to the map menu, which I wanted to add to the left of the map using the code I’d developed for other resources. This menu would provide lists of regions and dialect areas, allowing the user to select one to view it on the map rather than just clicking round the map. Vasilis had sent me lists of dialect areas and an XML file containing the hierarchical structure of regions and I spent quite a lot of time working with this data. I needed to ensure that the data presented in these files tied into the geoJSON data, and there were a few inconsistencies that took some time to sort out. For example, the ‘abbr’ element in the XML file did not always match up with the ‘abbr’ attribute in the geoJSON data and there were a few typos. Also, the regions XML file also contained dialect areas and I needed to strip these out. It took somewhat longer and was rather more tricky than anticipated to extract the data in a format that I could use, but I got there in the end. I think there’s still work to be done on both the hierarchical structure and the presentation, but it’s a start at least. The screenshot below shows the hierarchical layout of the dialect areas using a drop-down list:
I still need to add in a search option and I might replace the HTML select box with an alternative interface that can better display the hierarchy. As of yet it’s not possible to select an item and actually visualise it on the map, and this led onto another issue:
Selecting an entire region needs to behave differently to clicking on the map; when the user clicks on the map the regions that need to be highlighted are simply all of those regions that are present at this exact point on the map. But when an entire region is selected this may include several intersecting regions at various points within the region so (for example) ascertaining the centre of the selected region and working out which regions are present at this point would not give an accurate picture. I therefore needed a method to ascertain all regions that intersect with the selected region anywhere within the region.
I cam across someone else who had this same issue (https://gis.stackexchange.com/questions/170919/how-to-tell-if-a-geojson-path-intersects-with-another-feature-in-leaflet) and the answers pointed me towards the turf.js library, which I had also previously used for Speak For Yersel. I downloaded the most recent version of Turf (version 7) and wrote a test script to see whether it would work. However, I just couldn’t seem to get Turf to work with the geoJSON data – it just gave errors. I also tried plugging in the example given in the answer on the page linked to above and it also gave errors, which was very frustrating. Eventually I decided to try an older version of Turf (version 6) and both the example code and my geoJSON areas worked perfectly, so there much be something in Turf 7 that has changed. However, this means I can process all of the intersects using Turf 6 and store these as a cached list to be used whenever a region is selected from the lists. This will be my task of the start of next week.
Also this week I worked on the Books and Borrowing project. I now have access to the Stirling servers again and was therefore able to work through some of the outstanding tasks, although I won’t be able to update the online systems until the duplicate author work that another member of the team is working on has been completed (well, I could, but then I’d have to do it all again afterwards) so for now most of the updates are limited to the version of the site running on my laptop.
What I did manage to do was fix the weird apostrophe encoding issues across all data types, replacing the encoded apostrophes with regular straight ones. I’ve made this change on the live database, but until I regenerate the search indexes the online searches won’t be changed. I also replaced all curly apostrophes and double-quotation marks found in authors, borrowers, book editions, works, holdings and borrowing records with their straight equivalents. This took some time to implement and test as it involved updating several thousand records. All seems to have worked, though. Again, this change has been made in the online database and you can see the change when viewing records (see for example: https://borrowing.stir.ac.uk/search/0/0/0/advanced/brids|32203 where the text ‘Peveril of the Peak : by the author of “Waverley, Kenilworth”’ once had curly double-quotes).
I also removed ESTC from the search results filters (again, only on my laptop for now) and added in Book Work title to the search results filters (also only oh my laptop for now) as the following screenshot shows:
The book work titles are rather long, but I think it works ok and I’m sure will be a really useful addition. In order to implement this update I needed to update the Solr index structure to add a new field, reindex the data, update the API and the script that processes search results, so a fair amount of work, but worth it. I also still need to update the script that generates the Solr data to ensure it differentiates authors that have the same name, but I’ll wait to do this until the duplicate author work is complete. After that I’ll then grab a fresh copy of the online data, run it through the various stages needed to generate indexes and caches, test everything out on my laptop again, and after that I’ll need to get Stirling’s IT people to set up a new Solr index and import the new files. Once this has been completed I’ll then be able to update the online API and front-end.
Also this week I made some updates to the structure of the SpeechStar resource for Eleanor Lawson. These included some major changes of page URLs, which introduced some complexity as we don’t want people who may have cited a view of the old pages, or a specific video on one of those pages to end up with a ‘not found’. To avoid this I put in redirects from the old URLs, but this wasn’t enough as I also needed to ensure any filters were also passed over to the new pages, but this is all in place now. So for example, someone who has bookmarked or cited the ‘Child speech error database’, listing the videos by word, filtered by sound: k and sex: female with the video for ‘school’ open would have this link:
And rather than giving a ‘not found’ or redirecting to the default view of the page the above link continues to open the correct video with the correct filters.
Week Beginning 21st April 2025
It was another four-day week due to Easter Monday, and I spent a fair amount of my time working for Speak For Yersel. For our abstract for DH2025, I received some new, high-resolution images of the graphs from co-author Marc Barnard and after a little more tweaking and dealing with the submission process I was able to complete the submission process. I still need to actually sign up for the conference, though, which is something I’m hoping to be able to do next week.
One of the reviewers of our abstract had made a comment about user fatigue and enquired about how many users actually completed the surveys and this prompted me to undertake some investigation. I created a series of database queries that for each user extracted counts of the number of submitted answers in the morphology, lexis and phonology surveys. I then exported the data into Excel spreadsheets, one per region (Scotland, Northern Ireland, Ireland and Wales) and sent this data on to Jennifer in case it was of some use.
However, I did have to point out that the counts for each user are of answers submitted and some questions allow for multiple answers to be selected so there’s not an exact 1:1 relationship between the figures and the number of questions. Also, a user can complete a questionnaire more than once (or quit mid-way and then begin a second time). I noticed that there were a few users who have submitted many more answers than there are questions. For example, in the NI data there is a user who has submitted 102 morphology, 105 lexis and 76 phonology answers, even though there are only 34, 35 and 29 questions respectively. It’s not possible to ascertain exactly what prompted the user to submit so many answers, but it is perhaps a case of someone passing an iPad round a group of people.
I then decided to experiment with visualising the data, and for this I used the Highcharts library (https://www.highcharts.com/). There are lots of interesting visualisation that can be made with the data, and my first attempt was to generate a stacked column chart (https://www.highcharts.com/demo/highcharts/column-stacked). I decided that it would be useful to visualise all of the answers submitted by each user over time so wanted to plot each user as a column, with columns on the x-axis arranged chronologically by date of user account creation. Each column would then be split into three coloured sections showing the number of answers submitted across the three surveys (morphology, lexis and phonology).
I wrote a little script to generate the JSON data that Highcharts can easily work with, and adapted the Highcharts example linked to above to work with the new data on my local PC. The resulting graphs include a lot of columns (6379 for Scotland, 785 for Northern Ireland, 350 for Ireland and 1487 for Wales) and everything does get rather squashed together and some gaps can get lost, but what is interesting is how these graphs show the overall pattern of submissions. On the whole most users across all regions made a decent stab at completing all surveys, as there are clear bands of colours, admittedly with some variation and gaps. The graphs also show the outliers, especially the people who submitted many more answers than there are questions. One user in Scotland in particular seems to have gone a bit crazy, and this then causes the rest of the graph to be rather squashed.
Here’s the graph for Northern Ireland, showing a few users who submitted many more answers than there are questions, a few users who submitted very little, and an overall pattern showing users making a decent stab at completing all three surveys.
The pattern for Ireland is broadly similar, and with less users it’s easier to view the individual columns:
Wales has considerably more users, which means individual columns can get lost, but it’s still possible to get an overall sense of user completion rates:
For Scotland we have an awful lot more users, plus as mentioned earlier one user who submitted huge numbers of answers, which results in a graph that squashes up all of the other data:
I had to regenerate the Scotland data and graph as after my first attempt I realised that the Scotland resource features more than just the surveys but also features follow-on questions, quizzes and other activities and I hadn’t filtered all of this out. I was also interested to expand the x-axis to allow a more nuanced view of the data, and also to place a maximum extent on the y-axis to avoid one user affecting the display of data for all other users:
The resulting graph above (which you’ll need to open to view properly) demonstrates a lot more variation in user submissions that are lost from the smaller graph and demonstrates how the smaller graph with its big blocks of solid submissions doesn’t reflect reality. Having said that, the overall picture still shows a decent number of users submitting a complete or near-complete set of answers. Of course there is still much that could be done with the data. Even using the same stacked column graph, rearranging the users by number of submissions would be interested, and may demonstrate how the overall picture when presented in date order could possibly obscure the number of users who didn’t submit much data. But that’s for another time.
Also this week I made a few changes to the Speech STAR resource including adding a link to the ‘in clinic’ site form the top level tabs for Seeing Speech, Dynamic Dialects and the STAR site, as you can see here: https://www.seeingspeech.ac.uk/speechstar/. I also had a chat with Eleanor about the visibility of the STAR sites in search results.
I also made a few further updates to the VARICS lookup test that’s still in development, including updating the ‘how to’ guides and linking to them from the longer textual descriptions of measurements.
On Friday I had a Teams meeting with Katie, Matt and Kitt from the Books and Borrowing project to discuss the new versioning system I’m going to develop. We agreed that I will develop the full versioning system I specified in the document I sent around two weeks ago, and I’ll aim to get started on this in the next week or two.
Week Beginning 2nd December 2024
I began the week working for the Anglo-Norman Dictionary. I completed the task of importing 13 new XML source texts into the taxbase and I also continued to investigate the speed issues that still seem to be affecting the site. I figured out that while direct calls to the site’s API were pretty speedy, using the AJAX scripts to connect to the API (which the site does) was resulting in some lengthy loading times. This demonstrated that the issue was not the speed of the database or the server, but instead that there was some blockage occurring between the API and the public website. Further investigation uncovered that the AJAX calls were all being routed through the University’s web cache, which was not strictly necessary as both the site and the API are hosted within the University network. When I disabled this routing the speed increase was remarkable, and it’s a relief to get to the bottom of the issue.
On Tuesday I had a meeting with Deven Parker to discuss her playbills project. Her partners in Computing Science have made pretty amazing progress with getting ChatGPT to perform OCR on and extract structured data from the playbills images, and have so far processed around 4000 images. The AI tool has been able to divide the images into individual plays, extract titles, dates, theatres, actors and roles and also to assign genre to the plays. It has also been able to ascertain which list of person names are the actors and which the roles in each play, which is pretty amazing. I haven’t seen any actual data exported from ChatGPT yet, but apparently it’s all formatted as JSON so I should be able to work with it quite easily. The next step will be to arrange hosting for the project, although as the total collection of images numbers between 100 and 150,000 and takes up more than 700GB this might be quite tricky. I’ve submitted a helpdesk request to enquire about this but I haven’t heard anything back yet.
Also this week I had several email conversations with the Dictionaries of the Scots Language people about the upcoming rollout of the new dataset and some issues regarding citations that have multiple dates. Next week I’ll be processing a new batch of data for the dictionary. I also sorted out access to the web stats for the Speech Star website for Eleanor Lawson and fixed a glitch in the placenames CMS that Alasdair Whyte had spotted with his Mull site.
I also dealt with a discrepancy with the Books and Borrowing facts and figures that project PI Katie spotted. When looking at the stats for all libraries the number of borrowers listed in the first infobox was 11,194 whereas the number of borrowers mentioned in the occupations section was 11,197. This required a bit of investigation. The overall number of borrowers at the top of the page is calculated by adding up the borrowers of each gender at each library (Male, Female, Unclear and Unknown) while the number of borrowers in the occupation section was calculated from the total number of borrowers overall at each library. The discrepancy was arising because it turns out we have three borrowers in the system who don’t have a gender specified – their gender is set to ‘null’. They are therefore not getting picked up by the first calculation. As an initial fix I made the occupations count use the same figure as the count in the intro so at least things look consistent, but I then needed to assign a gender to the three erroneous borrowers and then regenerate all of the cached data for the site. This was a fairly lengthy process involving the execution of several data processing scripts and requiring the regeneration of the Solr index files. Once all this had been completed we actually ended up with 11,198 borrowers in the system as since the last cache generation a further borrower had been added.
I spent the rest of the week adding LiDAR data to the map interface I’ve developed for the place-names websites, starting with Ayrshire. The data comes from here: https://remotesensingdata.gov.scot/data#/list and the NLS have made it available (see https://maps.nls.uk/guides/lidar/#re-use) and it’s a fascinating resource to be able to incorporate. Adding it in required some pretty major reworking of the code for the map, but it has been more than worth it. The ‘display options’ map menu now contains an option to turn the LiDAR layer on or off, and if it’s on you can also change the opacity of the layer, thus allowing you to view whichever base map is selected. So for example, ‘Stair Mount’ is one of several ‘mounts’ that were created to commemorate military service in the 1740s. It appears on the OS 1881 map:
And can be viewed on the satellite photography:
But LiDAR lets us see several concentric circles that are not otherwise visible, plus other hidden details:
It’s really fascinating to just pan around the map looking for hidden features in the landscape and it has the potential to be a hugely useful research tool.
I also fixed a bug I spotted that was causing the exact map position and zoom level to be lost when sharing URLs of maps that featured search / browse results. In such cases the search or browse was being performed and the map would position itself to the extent of the search results rather than retaining the specific view, which was not especially helpful for people wanting to share specific views of the map like the ones above. Additionally, I updated the ‘display options’ to make the buttons in-line rather than being one per line which means the section takes up less space, as you can see in the above screenshots, plus I also updated the ‘Attribution and copyright’ pop-up (linked to in the bottom right of the map) to include information about the LiDAR data. I then applied this update to Iona as well. Unfortunately there is no LiDAR data available for Iona yet, but the other updates to the map interface were at least applied to this resource.
Week Beginning 25th November 2024
I completed work on and submitted the Speak For Yersel abstract for the DH2025 conference this week. The acceptance rate for this conference is pretty low so we’ll just need to see how we get on.
I spent most of the rest of the week working on place-names projects. We have a new ‘place-names of Nairnshire’ project starting up soon and I set up the systems for this project. The most recent version of the place-names CMS is one I’d developed for the Comparative Kingship project. For this version I’d migrated everything to Bootstrap so the interface has a nicer, more intuitive layout. However, since creating the CMS Bootstrap has made some significant changes to the layout of forms and in order to use the most recent version of Bootstrap I needed to go through the code and change a lot of things. For example, ‘select’ elements previously had the class ‘form-control’ but if this is used with the most recent version of Bootstrap then select boxes don’t have a visible down-arrow to make it clear there is a drop-down list. In order to make this appear the class needs to be changed to ‘form-select’.
I’d also set up the CMS to be bilingual, with fields for both English and Gaelic forms, as this was required for Iona and Mull. However, this is not necessary for Nairnshire and I therefore updated the interface to remove the Gaelic boxes, which makes things a lot more streamlined. Once I’d completed work on the CMS I then replaced the Comparative Kingship CMS with the updated code, as it too didn’t need all of the Gaelic fields.
I then imported the data for the Nairnshire parishes from the GB1900 crowdsourced data. It took some time to get this set up as I had to redownload the full GB1900 dataset and import it into a new database. With this in place I could then extract the data for the new parishes, resulting in several thousand place-names getting added to the CMS, plus links to the OS second edition source and the creation of historical forms. What I haven’t been able to do yet is set the altitude for these place-names as I’m currently setting everything up on an instance hosted on my laptop as the new domain for the project has not yet been set up. My Google Maps API (used for requesting altitude data for a given latitude and longitude point) will only work from sites hosted on ‘glasgow.ac.uk’ so connections from my laptop are refused. Once the domain is set up I’ll ensure this data is generated. I also began working on setting up the ‘map first’ interface for the project’s front-end but again I’m limited in what I can do here until we get the actual domain set up – hopefully next week.
Also for place-names this week I investigated an issue with the Fife place-names resource that Carole Hough had spotted: a browse by classification code was resulting in a blank screen. Thankfully no other part of the site was affected and once identified it was relatively easy to fix the issue – something that had been introduced during the migration of the site to the new server and had previously been overlooked. I also looked into an issue with the Ayrshire CMS that Simon Taylor had identified.
Also this week the AND people sent me 13 new XML files that needed to be added to the Textbase. This is quite a lengthy process as I need to check the texts are in the correct format, rename and upload them and then run them through multiple stages in order to assign genre, link to the lists of source texts, extract individual pages to enable the jumping to a specific page and then generate all search data for the texts for the concordance view (e.g. KWIC). I only got round to working on this on Friday afternoon and I still have more than half of the texts left to tackle, which I’ll do next week.
There was another AND related issue I investigated this week. The site has been running rather slowly recently and I asked our IT people to investigate this. The most noticeable issue was that when loading in a dictionary entry the links to source texts appear as IDs only. The full text details for these are then loaded in via an AJAX call, but this call was taking more than 20 seconds to complete, when previously it was happening instantaneously. I did some investigation and realised that the API call was including a lot of fields that were not actually needed on the entry page, such as lists of items for each sigla, bibliographies and notes. I therefore created a new version for the entry page that only outputs the two fields that are used (slug and siglum) and this now loads much more quickly. We’ll just have to keep an eye on the overall speed of the site as it would appear that the server is struggling somewhat.
In addition to the above I had an email conversation about the hosting of the OHOS project website, made a couple of tweaks to some data and investigated web statistics for Eleanor Lawson, spoke to Garric Allen about another new proposal he’s putting together (for the AHRC this time) that I’ll probably be involved in, and had a chat with William Ashford of the DSL about the ancillary pages we host on the live and development sites.
Week Beginning 11th November 2024
Last week I was sent the latest dataset from the Dictionaries of the Scots Language’s editing system that included fixes to the way citation dates were generated and the reinstatement of the bibliographical data structure that my scripts were written to work with. On Monday I ran this updated dataset through my import scripts running on an instance of the DSL site hosted on my laptop and all went very smoothly.
The new bibliographical data contains 7045 entries (4794 SND, 2251 DOST), up from 6108 in the live data (4099 SND, 2009 DOST). The new data features 5348 authors, down from 5434, and 9791 titles, down from 9908.
When I processed the previously exported dataset a couple of weeks ago I spotted that there had been an issue with the generation of the citation date elements during the export process, which meant that almost 29,000 entry citations featured no date field. Thankfully this issue has been successfully resolved in the latest export and the number of citations featuring no dates had dropped dramatically to just 56.
With both the export from the DSL’s editing system and the import of the data into the website system now working smoothly we are in a position to roll out the update on the live DSL site. The DSL team still have other things to do before this happens, however, and we’re likely to not go live with the update until the new year.
I spent a large part of the week continuing to work on the interactive map of the correspondence of Robert Burns, and I have now fully completed a first version of the resource. Last week I worked on facilities to enable specific views of the map to be bookmarked, shared and cited by adding information about the view to the hash in the page URL. This week I completed work on this by enabling a specific timeline entry to be shared. I was worried that this would be rather tricky to implement as the timeline data is loaded in sequentially each time the user chooses to proceed to the next item and initially I had been intending on loading all correspondence for prior timeline items when a specific item was loaded from a URL. Instead I decided to not feature the earlier data on the map until the user navigates back through the items, much in the same way as later timeline items are added. This was simpler to implement than populating the map with every earlier item, and the timeline is primarily meant to be accessed using the ‘previous’ and ‘next’ buttons rather than by manually moving about the map so I didn’t think this was a huge issue.
Whilst using the timeline feature I realised that it was somewhat difficult to return to the full map data once the timeline tab has been pressed on. When a user enters the timeline the map is cleared of data and each correspondence is then added to the map in date order as the user navigates through the timeline items. But pressing on another menu tab leaves the contents of the map at the point at which the user left the timeline, meaning not all data is necessarily visible. The only way to return the full dataset to the map is to reset it or re-apply a filter, which is not very intuitive. I therefore added an ‘Exit timeline’ button to the timeline view that when pressed on reinstates the full dataset that matches the user’s chosen filters and returns the user to the ‘Filter’ tab. You can see this new button in the following screenshot:
Also visible in the above screenshot is the new ‘Cite’ button, which I added to each menu tab and also to the bibliography popup. When pressed on this opens up a popup with various citation styles and the text of the citation varies depending on what you’re viewing, as the screenshot below demonstrates (with the URL of the resource redacted as it’s not ready to launch yet). The screenshot shows that the view of the map if filtered to only show ‘historians’, the map uses the ‘historical’ base map and the ‘filter’ tab is visible.
Citations of the bibliographies are handled slightly differently as the biography is already in a popup. For this reason when you press on the ‘cite’ link the existing popup content is replaced with the ‘cite’ options, with a link back to the biography rather than opening a further popup. I also implemented a URL shortener that I developed for another project, which essentially stores a short code in the database to represent the full URL. The short code is then used in the citation, and can be shared. When the short code is passed the full URL is retrieved and the relevant view and data are loaded.
I then updated the filters tab to include includes options to view the data in a table and download the data as a CSV, as the following screenshot demonstrates:
Again I was thankfully able to adapt existing code from previous projects to implement these options, although I did still have to spend some time customising things to ensure that the data was properly formatted in the CSV and the in-page table view. I think that is now everything in place and it’s now time for others to test out the resource and give me some feedback. I’m sure there will be at least some things that will need tweaked, or some bugs that crop up.
Also this week I had an email conversation about the hosting arrangements for the OHOS project and also set up a new user for the project’s website. Eleanor Lawson sent me some further updates to the STAR website, consisting of some improved animation videos and I ensured the older versions were successfully replaced with the new ones. I also had a chat with Jennifer Smith about the DH2025 conference and whether we should write a paper about the new Speak For Yersel regions for it. I’ll need to give this some further thought next week.
Week Beginning 2nd September 2024
I was off work sick on Monday and Tuesday this week, but thankfully I was feeling well again by Wednesday. On Wednesday I had a meeting with Katie Halsey and Matt Sangster about an article we’re going to write about the Books and Borrowing online resource. We now have an overview of what we’re going to write about and will try to have a first draft written by the end of the month. I also had to spend a bit of time investigating some speed issues with the Books and Borrowing website. One thing that may have been contributing to this was a call to the API that isn’t used in the front-end but was being submitted by a web crawler. The call was returning details for all library registers in the system, resulting in a query that was taking around 13 seconds to execute. The endpoint is only ever used in the front-end with a library specified, which is a much quicker query and I therefore blocked the endpoint from running if a library isn’t specified.
On Thursday I had a meeting with the Rangar’s Islands project (https://blogs.nottingham.ac.uk/ragnasislands/). The project is based at Nottingham and they’re putting together a place-name database for three of the Orkney Islands. They’d like to use the system I’ve created for other place-name projects such as Iona and we met to discuss how this might come about. The project will be applying for funding to develop the front-end and all being well I’ll be involved in setting this up.
Also this week I made some further tweaks to the new date search facilities of the Dictionaries of the Scots Language. The team wanted the date range that is visible to the left of the sparklines in the search results to default to the limited range reflected in the sparkline text rather than the actual first and last dates of attestation. So for example a DOST entry with dates from 1175-1780 would not show these dates but would instead display ‘<1375-1700+’. Implementing this wasn’t as straightforward as I’d hoped it might be. The Solr index contains the first and last dates of attestation, and it’s these that are used to display the dates. However, I couldn’t update them to something like ‘<1375’ or ‘1700+’ as these dates are used in the filter options and need to be valid integers. I did consider updating the Solr index to store the amended first and last dates as new fields, but this would have meant updating the structure of the Solr indexes, plus another regeneration of the Solr data. Instead the results script picks out the first and last dates from the sparkline text on the fly, taking into consideration any ‘<’ in the first date, ‘+’ in the last date and ensuring only one date is displayed if ‘from’ and ‘to’ are the same.
I’d also spotted a bug in the search when a phrase was searched for that wasn’t surrounded by double quotes. This was bringing back some very garbled results. To fix this I needed to update the search results page to ensure such searches were analysed and surrounded by double quotes if these were needed prior to sending the request to the API. Implementing this was also rather trickier to fix than I’d hoped. I couldn’t just add quotes if the query had a space as I also needed to check for Booleans. If these are present then we definitely don’t want quotes to be added. Also the query string includes all of the other bits that appear after the phrase (i.e. /quotes/full/both/full) so I couldn’t just surround the entire thing in quotes but instead needed to extract just the phrase, add quotes then add it back to the whole string. However, I managed to get it working and the results returned now make more sense.
Also this week I had email conversations with Joanna Kopaczyk and Gerry Carruthers about new (separate) proposals they are putting together that I will be a part of and arranged to meet Garrick Allen to discuss a proposal he is developing. I also replaced a couple of videos on the various Speech Star websites at the request of Eleanor Lawson.
I spent the remainder of the week working on the Burns Correspondence map, mostly on the API and queries and planning on how the map interface will function, specifically the lines joining locations. Displaying all of the lines swamps the map and is just too much information to display at once, so I’m going to have to think about how best to proceed. The screenshot below demonstrates just how busy the map gets with all of the lines on:
I’ll continue to think about this next week.