Category: Misc
Week Beginning 20th July 2026
I worked on Thursday and Friday this week, having taken the other days off as a holiday. Whilst I was away there was an issue with the server on which we host a lot of our important websites, meaning they were unavailable from Sunday afternoon until about 5pm on Tuesday, and I had to spend some time liaising with Luca about what should be done and responding to users and project members who were unable to access the sites. I also had to spend some time once I was back updating everyone on the situation, and on Friday afternoon Luca and I met with Mike Irwin from IT Services to discuss the situation and what we could learn from it. Hopefully we have a plan but we’ll just need to see how things work out in future.
Over the weekend the Burns Supper Map (https://burns-supper-map.gla.ac.uk) had its official launch (thankfully this website is not hosted on the server that encountered issues) at the Burns Birthplace Museum. As I was away on holiday I wasn’t able to attend, but I was kept updated by the project team and it all went very well. After the launch a few more suppers came in, and some existing suppers needed their details updating, for example because their title was not quite right, or their position on the map needed tweaking, or further photos were submitted. I spent some time on Thursday making these updates. I also exported the data for the Old English Thesaurus as CSV files, which are going to be submitted to the Oxford Text Archive, responded to some queries from the Dictionaries of the Scots Language team and made a minor tweak to the parts of speech section of entries on our test server.
Other than my meeting with Luca and Mike during the afternoon, I spent most of Friday working on the travel routes for the HiMuJe Malabar project. I had been sent data for three travel routes to add to the map to test the travel route system I’d previously developed.
I updated my map code to link directly to the data source for the map that is generated from the digital edition and hosted at the University of Jena, so that new updates to places will automatically get pulled in. I also updated the code so that when you select a route from the menu the map displays the full extent of the route, which I think will be very helpful.
Some of the places that appear in the travel itineraries are not yet found in the places file, or are found but do not yet have location data so for now I’ve had to remove these from the travel routes. This isn’t a huge issue though, as for now the routes are really only for test purposes and I can add the missing locations in once they are available.
By the end of the week I’d added the three new routes to the map, although there is still a lot of work that needs to be done. For example, the colours used for the markers and routes are still not finalised and we’ll definitely need to ensure the route colour is not also used for a polygon. Currently Malabar is red, and so is the route, which makes things very confusing. I also need to work on the menu to break it up into sections by type and assign different colours to the routes (or possibly the types). But here is a screenshot showing the full extent of one of the trade routes:
I also had an email conversation with Tom Bartlett about a podcast site he created a while back that he would like to migrate to the University system. I’m going to have a meeting with him about this, hopefully in the next few weeks. I’m on holiday again next week and some of the following week, so it will be a while until my next update.
Week Beginning 13th April 2026
This was my first week back after my Easter holidays and I returned to discover that one of my oldest sites had been flagged with security issues. I created the Emblems sites (https://emblems.arts.gla.ac.uk/french/ and https://emblems.arts.gla.ac.uk/alciato/) more than twenty years ago and the way they connected to their database sources was obsolete and could be exploited. This wasn’t a huge issue as no personal or private data was stored in the database anyway, but it still wasn’t ideal and needed sorting. It would be good to completely overhaul these resources as they are still actively used as research tools but their interfaces are somewhat creaky now. I don’t have time to do this at the moment, unfortunately, so instead I focussed on replacing all database calls with a more modern solution and ensuring all user submitted content is fully sanitised. This in itself took two full and pretty intense days to sort out. I tackled the French site first and when that was sorted I’d hope I’d be able to replicate these updates on the Alciato site, which I could do to a certain extent. However, the latter site has several additions to its data and functionality so it was not possible to simply replace the entire code, and each script needed to be checked and manually updated. Thankfully it’s all done now and both sites should be useable and safe for the foreseeable future, even if they still look a bit ancient.
I then spent a couple of days continuing to work on the Burns Supper map, working through my list of ‘to do’ items for the project. I started off with processing a spreadsheet to update supper venue titles and delete certain suppers that had been flagged as no longer needed (usually duplicates). I then wrote a further script to reassign images from one supper to another, which involved renaming images and updating database records to process the reassignment. I then updated the advanced filters in the front-end to enable suppers with images and videos to be filtered independently. Previously there was one filter for displaying suppers that featured (or didn’t feature) media files but I reckoned it would be useful for people to find and display just those suppers that feature videos. Now there are options for selecting suppers with images, suppers with videos or suppers with no media, and it’s also possible to combine these (e.g. showing all suppers that have either images or videos).
I also removed the ‘Download CSV’ option from the map as it was decided that we would not offer such a facility, and I added in a copyright statement that appears underneath the media carousel. I updated the ‘Share’ options to add in LinkedIn and BlueSky and remove X, and added in the welcome message on the ‘Home’ tab.
With these updates in place I then focussed on updating the user interface. At our last meeting we’d agreed that we’d mostly use elements from the first test interface I created (as shown in my post from a couple of weeks ago) but that we’d use the font I’d selected for the second test interface. It took several hours of implementing and testing to get the new interface working, but it’s now in place, as you can see in the following screenshot:
I then created the image slideshow, which appears as a button on the ‘Home’ menu. The slideshow picks a random selection of up to 20 images from the suppers that are currently displayed on the map (i.e. it takes any filters into consideration) and displays them in a slideshow that automatically scrolls (but pauses when your cursor is over the image). An image caption consisting of the venue and country of the supper plus a link through to the full record for the supper also appears, as the following screenshot demonstrates:
Each time you load the slideshow a different selection of images is pulled in, and I think it’s quite a nice feature to use. Note that there are often black bars visible as the images are all different dimensions and have to fit in the same overall space. I think it looks ok, though.
Other than adding help and about text and attribution text the only thing left to tackle now is the facts and figures popup, which I’m hoping to look into next week.
Also this week I spent a little bit of time working for the Dictionaries of the Scots language, updating the user survey popup based on requests for updates I’d been sent. I also set up a new subdomain for the Mapping Metaphor project, which I’ll use for the redevelopment of the site, which I’m hoping to start work on next week.
I spent more of Friday beginning to work on Joanna Kopacyk-McPherson’s DOST Auld Laws project. This project has around 500 pages of handwritten and printed text that has been transcribed using the Transkribus tool, and I need to create a front-end to allow this to be browsed, searched and viewed. My first task was to export the Transkribus text as TEI XML, something that I thankfully managed to achieve. I then spent some time familiarising myself with the texts and thinking about what technical solutions should be used to create the front-end. We are going to need to display images and text and highlight sections of text in the images (and vice-versa), which is not something I’ve ever tackled before, so it’s going to take some time to get my head around.
Week Beginning 30th March 2026
This was a three-day week for me because Friday was Good Friday and I’d taken the Thursday off as well. Despite this, I still managed to work on four different projects. Last week for the Playbills project I’d written a script to process performer names, including splitting this up into titles, forenames, surnames and other names, and also assigning gender. What I’d spotted and hadn’t had time to address is that there are several thousand performer names that are actually multiple performers that would need to be split into individual people. I spent most of Monday working on a script that would split these multiple performers up and process them all individually. This managed to reduce the number of unprocessed performers from 1271 to 414 (and most of the ones remaining are either blank or have text like ‘performer unknown’). I saved all performers in spreadsheets so Deven can check them – as of yet I haven’t made any updates to the database. There are 48,234 individual performers that were successfully processed by my script and a further 3,491 that were processed from multiple performers, leaving just 414 unprocessed performers, so I’m pretty happy at how successful my scripts have been.
Also for the Playbills project this week I had further discussions with Deven about downgrading certain plays to ‘special attractions’, which are things like songs and dance that are not full plays. Deven had also completed work on the spreadsheet that mapped out which performances involved the same plays (even if their titles were not exactly the same) that I will use to generate canonical records for plays. This spreadsheet also notes which plays should be downgraded and others that should be deleted entirely.
Whilst working on the scripts that will generate canonical records, downgrade plays and delete others I spotted some issues with the spreadsheet, such as plays being marked for deletion that looks like legitimate plays to me. Some other rows in the spreadsheet had been marked as both to be merged and deleted, which wasn’t right. I sent a list of possible issues to Deven and I’ll need to take this up with her once I’m back from my holiday.
For the Burns Supper Map project I had an in-person meeting the Cleo and Pauline to discuss the map, the interface, the data and our plans for the weeks ahead. It was a great meeting and really useful to meet up in person. Everyone is very happy with how the map interface is coming along and we have decided which of the test interfaces I’d developed would be used for the live site (mostly the first test interface but with the fonts from the second one). I have a 14 point ‘to do’ list for the project that I’ll work through once I’m back from my holiday.
For the HiMuJe Malabar project I wrote a non-technical specification document for the map I’ll be developing for the project, based on the discussions I had with Renu and Ophira at our meeting last week. I’ve got a pretty good idea about what needs to be developed now and I sent the first draft of my document to Renu and Ophira for feedback.
The remainder of my time was spent trying to digitise an old cassette tape of Scots and Gaelic poetry for Alan Riach in Scottish Literature. I had hoped I’d be able to plug an old tape player into my laptop to do this, but then I realised my laptop (and most modern computing equipment) doesn’t have a line-in port so this wouldn’t work. I then asked Jane Stuart-Smith whether there may be facilities in the GULP lab that I could use, and while there was a tape player we were unable to get it connected to any computer in the lab. I finally managed to digitise the tape by digging my old Hi-Fi out of my attic at home and plugging it into an old PC. Thankfully this worked and I recorded each individual poem as a separate MP3, then sent these to Alan.
I was off on Thursday and Friday, and I’ll be off for Easter for all of the following week and will return to work on Monday the 13th of April. So that’s all from me for now.
Week Beginning 23rd February 2026
I continued to work on the Burns Supper Map from Monday to Wednesday this week, with my first task being to import the public domain data into the map, taking the total number of suppers on the map to 751. I then implemented the advanced filter options. You can now open the advanced filter popup and select any of the filters you’re interested in. When you press the ‘apply filters’ button at the bottom of the popup it closes and the map displays only those suppers that match your criteria. The ‘Advanced’ section of the side menu then displays the number of matching suppers, your selected filters and buttons to refine or choose new filters, as the screenshot below demonstrates:
Note that I haven’t done any work on the colour schemes for the map yet – it’s all just using the colours taken from the Iona place-names map, but this will change. I also updated the map so that both the advanced filter and regular filter options now reposition the map to show all matching suppers when selected. However, icons on the left of the map can get obscured by the map menu. It has a tendency to sit on top of the US. I’m not sure what to do about this – I could ensure the map zooms out further, or I could close the side menu, although this might just confuse people.
I also updated the non-advanced filters section so that it displays the total number of suppers. However, a supper may have multiple filter options in a filter type so this total will not be the same figure as adding up all of the counts for individual options (e.g. one supper can have multiple toasts so will appear in the count for each individual toast that it features). I then created the table view. Pressing on the ‘Table view’ button will display all suppers currently found on the map in tabular form, and you can reorder the rows by pressing on a heading (e.g. ordering the rows by country). Pressing on the venue name link closes the table view, centres the map on the supper and opens the supper’s in-map record. Note that if you’ve performed a filter then the table only contains the filtered data.
Setting up the advanced filter option was especially time-consuming to implement so it was good to get that finished. There’s still a lot left to do, such as ensuring filter options get added to the page URL to enable bookmarking / sharing / citing of specific results. This is going to be another big job, and one that I’ll hopefully tackle next week.
I also spent some time this week drafting some text with Luca for a page about the technical developers across the College and the services we offer. This is not yet live, but will be a useful information point for staff who are looking to create an online resource for their data.
On Tuesday this week I participated in a meeting to discuss a new proposal being led by Sara Pons-Sanz at Cardiff that Glasgow will be involved with. It was a useful meeting and we all have a clearer idea about what the project will entail and how Glasgow will contribute. I had a further meeting on Friday with Jennifer Smith and Janine Illian about statistical analysis of the Speak For Yersel data and it looks like we’ll be getting some people in statistics working with our data, which is great.
I spent the remainder of the week working on the Playbills project. I’ve begun to set up an API and pages that will allow people to browse the playbills data. We still have a lot of work to do with the data, such as creating single, canonical records for venues, plays and other data types, so it’s likely that all of the data will need to be replaced at some point, but as the data structures are mostly finalised I decided to start work on some aspects of the front-end. So far I’ve created pages for browsing venues, listing playbills and browsing genres. I hope to continue with this next week.
Week Beginning 16th February 2026
On Monday this week I had a meeting with Joanna Kopaczyk and Pia Lehecka to discuss the DOST source materials transcription project. The materials have all been transcribed using Transkribus and the project needs a front-end created through which the images and text can be searched and browsed. A mockup interface has already been very kindly produced for us by Dario Kampkaspar, who created a pathway for converting Transkribus XML to TEI XML (see ‘Page2tei’ here: https://help.transkribus.org/downloading) so hopefully it won’t be too difficult to create something similar for the entire dataset, as task I’ll need to have completed by the end of May.
On Tuesday I had a meeting with Deven Parker regarding her Playbills project. We met with a PhD student in Computing Science who has been developing the pathway for sending playbill images to AI and processing the files that are returned. We needed to make a few tweaks to this pathway, and also to figure out how we can run things ourselves and it was a really useful meeting to participate in. After the meeting Deven and I had a further meeting to discuss the data extraction and processing I’ve been doing, and subsequent data cleaning and amalgamation tasks that will need to be undertaken. Deven is going to try and proofread and correct the YAML files that were originally generated by the AI as an initial step, and this will mean I’ll need to delete my data and regenerate everything from this updated dataset. I can’t therefore do much with the data I currently have, but will instead focus on developing the methods for browsing the playbills in the front-end, something I’ll begin working on next week.
I also met with Louis Strange on Tuesday this week to discuss a new proposal he’s putting together. It was a useful meeting and I gave him some advice about possible ways his data could be presented and used online. I can’t say much more about the proposal at the moment, but hopefully it will be funded.
Other than meetings, I spent quite a bit of time this week working on the interface for the new interactive map of Burns Suppers. I set up the basic map interface (using a satellite map with labels) and set up the map menu using the components I created for the Iona place-names project. For now the side panel has the same colours as the Iona map, but this will be changed in time.
My first task was to ensure that all of the supper records could be loaded into the map, and these work with the clustering tool. Currently the map marker is the same as the old supper map (red background, knife and fork icon). I did try using a haggis icon that we found online, but it’s not really going to work as when scaled down to a suitable size it just looks like an indistinct blob. I also tried using the Font Awesome ‘lemon’ icon as it looked vaguely like a haggis, but I’m not sure this is ideal either. We’re going to need to give this some further thought.
I added in all of the textual information about the suppers to the record popup and the map is already beginning to shape up quite nicely. I then added in a facility to allow you to bookmark / share exact views of the map (position and zoom level) using the Leaflet Hash plugin. Eventually the URLs will also feature filters etc but I haven’t implemented that yet. But I have implemented the filter options themselves, all of which should now be working. If you press on the ‘Filters’ menu item you should now see some text about the filters and a drop-down list featuring the various filter types. I realised my specification document hadn’t included number of guests as a filter type so I’ve added that in too. One you select a type (e.g. ‘Poems and songs’) the individual filter options are listed, together with counts of the number of suppers that feature them. You can then press on an option and the map will update to only display the matching suppers. The screenshot below shows the map with ‘Tam o’ Shanter’ selected. Note that as of yet the map doesn’t zoom and pan to ensure all matching suppers appear in view – instead the map just stays where you previously had it. I’m not sure now whether making the map automatically change position is a good idea or not, so it’s something to think about.
I also updated the ‘Home’ menu to add in the title of the resource and to make the buttons work. The ‘help’ button now opens a popup with some placeholder text while the ‘reset’ button resets the map to include all data and the default position and zoom. I’ve updated this as previously it was zoomed in on Scotland. Now the map is zoomed out and shows much of the world (depending on your screen size). I also ensured the ‘Attribution and copyright’ link in the bottom right now works, displaying a popup with some placeholder text, and I’ve added some text to the ‘Advanced’ menu section, although the advanced filter options are still to do. I also tested all this on my phone and everything currently in place works fine on it. Next week I’ll probably work on the advanced filter options, which will allow users to combine different filters.
I spent most of Thursday updating the APIs for various sites, as Luca had spotted some inefficiencies that could be improved. I’ve now updated all of the APIs that we host locally, but I still need to implement the changes on our externally hosted sites.
On Friday I worked for the Dictionaries of the Scots Language, investigating some non-urgent issues with searching that had been sent to me in November last year. It turns out that these issues are all sorted with the new DSL interface we’re hoping to launch this year, so I didn’t need to make any changes to anything. I also made some updates to the layout of some aspects of the new tags on the new DSL website, and the rest of my time was spent making further tweaks to the new DSL website that have been on my ‘to do’ list for a while.
I’d spotted that the search results in the side panel on entries was including blank links that would be highlighted when hovered over and I managed to identify the issue and sort this now. It turns out I’d already sorted this for searches that involve both SND and DOST, but hadn’t applied the update to individual dictionary searches. I also created a new version of the bibliography page that lists the actual quotations as well as providing links to the entry pages. I can’t really share any screenshots of this for now, and I don’t know if we want to include the quotations or not, but I thought I’d create this test version so we can see how it might work.
I also made the links from the bibliographies on both the test version and the main version take you to the actual quotation within the entry, rather than dumping you at the top of the entry. I used our purpley-pink highlight colour to highlight the citation to make it easy to spot which one brought you to the entry. This actually took quite some time to implement as a bibliographical item can be cited multiple times in an entry and in such cases the system needs to know which one to link to, but I reckon linking through to the actual quotation from the bibliograph page will be a hugely useful addition.
Week Beginning 2nd February 2026
I had a bit of a disrupted week this week, as I started feeling unwell on Tuesday morning and ended up off work sick for the rest of Tuesday and Wednesday. During this time I felt absolutely wiped out and could barely do anything other than sleep, but by Wednesday evening this had developed into a monstrous cold, the likes of which I’ve not had for several years. Thankfully once the symptoms had moved to my nose and throat my head was a bit clearer and I was able to work on Thursday and Friday, but I was still pretty far from feeling 100%.
I spent most of Monday this week preparing for, travelling to and co-presenting a talk about Speak For Yersel at the Edinburgh Futures Institute with Jennifer Smith. The talk went pretty well and it was good to meet some of our linguistics colleagues at Edinburgh, plus others involved with the EFI. I spent some of my other available time reading through and commenting on an AHRC proposal that will involve Glasgow and the Historical Thesaurus that had been sent by Sara Pons-Sanz at Cardiff University, and looking through some further place-name data I’d been sent for the Place-names of Armagh project.
Despite being off work sick on Wednesday I still managed to attend an online meeting for the Burns Supper Map project to discuss the specification document I’d prepared for the project. This was all very positive and there weren’t any major issues that anyone had spotted whilst reading through it.
For the remainder of the week I spent a bit of time investigating some issues that had been encountered when publishing pure xref entries through the Anglo-Norman Dictionary’s management system. Certain cross references were not appearing in the published entries despite being in the XML and a bit of investigation uncovered why. The entries contained cross references to entries that don’t actually exist in the dictionary. For example, Mars_2 references ‘march’, which is not an entry and respundre_2 references ‘repundre’ which is also not an entry (they both need homonym numbers added). When xref entries are published the cross references are extracted and stored, and at this point the system checks that the references are valid, and only links to entries that are valid. It is these that are displayed in the front-end, so even though invalid xrefs may exist in the XML they don’t get displayed. The ‘preview’ generates its view directly from the XML without checking validity, which is why this view doesn’t match the front-end. I ran a check and it turns out that there are around 500 xref entries that include a reference to an entry that doesn’t exist, and I passed these onto the editor who will get these sorted.
On Friday I met with Jennifer and Janine Illian, who is the current Head of Statistics, to discuss the Speak For Yersel data and what kind of additional statistical analysis might be possible. Janine is particularly interested in spatial modelling and has a keen interest in linguistics and it was really great to hear her thoughts about the Speak For Yersel data. I’m going to send her the data for all survey responses next week so she can experiment with it, and we’ve arranged to meet again later this month.
I spent the rest of my available time this week working on Deven Parker’s Playbills project, working with the YAML files, figuring out how these might be imported into Solr and how we can extract canonical records for things like venues from them. It turns out that Solr can’t index YAML files (at least not without creating a custom data importer), which is a bit of a surprise. This isn’t a major issue, though, as I can convert them to JSON, although this also proved to be trickier than I’d anticipated. Normally I’d use PHP to process data, but PHP also can’t read YAML files, at least not without installing extensions and this process seemed far too convoluted to bother with. Instead I used Python to convert the files, but this involved a bit of trial and error as I’m not used to Python and it’s bizarre insistence on whitespace being important, and the fact that if you mix up spaces and tabs to create this whitespace the scripts fall over. I got there in the end, though.
The bigger issue I encountered was with the unit of data that gets indexed. I’d previously said that we’d index entire playbill files and use ‘playbill’ as the smallest item that gets returned in the search results, but it turns out there are some problems with this, and I think indexing individual plays is going to work better. I’m still experimenting with the data and Solr’s capabilities, but initial impressions are that it isn’t very good when working with subsets of data within individual files, or more complex queries. For example, you can search the playbills for the title ‘Macbeth’ and find matching playbills. But if you combine this with another field that exists in another play in the playbill (e.g. role ‘Jacques Strop’) the playbill record will still be returned. So even though the role mentioned actually belongs to a different play in the playbill, because both pieces of information exist somewhere in the playbill it gets returned.
With my initial experiments Solr also flattened out the data – all performer names appear in one list per playbill, not separate lists per play, and it’s the same with roles. Other than the order of the items in the lists, there is nothing to connect the two. The following screenshot shows one playbill record indexed within Solr (just using Solr’s default post and without customising a schema). You can maybe see how Solr has flattened things out, resulting in data being lost (e.g. which performer belongs to which play).
I then tried to index the data at play level, adding in a play ID and also any playbill level data (thus ensuring it’s still possible to search for date, venue etc). You can see the results in the following screenshot, which includes 5 separate records.
Here at least it’s possible to tell which performer / role belongs to which play. But performers / roles are still only connected by their position in the lists. Record 5 is a duplicate I made of record 4, but I deleted the ‘role’ text for one performer to see what would happen. And Solr indexed the record as it was, with 5 performers and 4 roles, so based on list order ‘Miss Newton’ is now ‘Landlord’ and not ‘Marie’, and ‘Mr. Watkins’ now had no role.
After further investigation I realised that it is possible to get sole to properly index nested data (see https://solr.apache.org/guide/solr/latest/indexing-guide/indexing-nested-documents.html) although instructions on how to actually import nested data into Solr are pretty thin on the ground – you can’t just use the default ‘post’ command as this flattens all data. I ended up following another tutorial (see https://docs.arenadata.io/en/ADH/current/how-to/solr/solr-index-nested-docs.html) and importing the data using the Solr admin interface. This thankfully worked, as the following screenshot demonstrates. You can see that individual performers are directly associated with roles.
There’s still a massive amount to do with the data, though. I need to extract unique venues, plays, performers and roles and assign IDs to them to enable them to be searches for. I decided that it would be easier to manage such processes via a relational database, so on Friday and mapped out a structure for the playbill data and bean working on an import script that would process the JSON files. Lots more to do in the coming weeks!
Week Beginning 12th January 2026
This was my first proper week back at work, having spent most of last week travelling and attending a workshop in Zurich. I spent a bit of time working on the Bilingual Thesaurus of Everyday Life in Medieval England, looking into issues that had cropped up at the workshop. Someone had spotted that the start and end dates for some lexemes appeared to be the wrong way round and last week I discovered there were 197 such cases. I had an ongoing discussion with the project PI Louise Sylvester about this. She sent me a spreadsheet that contained updated data for the thesaurus, with the idea being that we could check the erroneous dates against this. However, the spreadsheet was created for a later project than the BTH and had both a different structure and different data. For example, some categories in the online BTH were not included and many categories in the spreadsheet featured different or larger numbers of lexemes. The dates were in a different format, featuring ‘ante’ and ‘circa’, plus a question mark to denote other uncertainty and a plus to denote continuation. The BTH features none of this – just start and end dates. The spreadsheet also featured no links out to the MED and the AND, only links to the OED. We did wonder whether we should replace the online BTH with the data from the spreadsheet but all of these issues mean this just wouldn’t work. Instead we decided that I would (at some point) write a script to identify lexemes in the spreadsheet that are not in the online BTH and we can see about incorporating them. In the meantime I fixed the 197 lexemes that had their dates the wrong way round.
Also for the BTH this week I implemented an option to order the lexemes in a chosen category alphabetically, by first attested date or length of attestation (within the AN or ME section), where previously all lexemes were ordered alphabetically within each section. This is something that was raised at the workshop, and something I wanted to implement as it’s a useful feature. I’d already included this option in the main HT and parts of the code for it were lurking in the BTH code in an inactive state, although I needed to rework this as the main HT handles dates in a more complex manner. The update required changes to the database, the CSS, the PHP and the JS scripts, but it’s all now live and the site remembers your choice during your session, so if you select ‘length of attestation’ in one category and then navigate to another this is remembered. Below is a screenshot showing a category with the lexemes ordered by length of attestation:
This week I met with Jennifer Smith to discuss the talk we’re giving about Speak For Yersel in Edinburgh in a couple of weeks. We had a good chat and made a plan about writing our respective sections. I then spent about a day preparing the slides and text for my section and sent everything over to Jennifer so she could work on her parts.
Also this week I did a little bit of work for the AND, updating links from AND entries to the DMF, as their site has changed, which broke all our links. I thought I’d found a way to link through to their corresponding entries but unfortunately their URLs now include a session variable that expires after a while, and the URL doesn’t work without a valid session. This means it’s not currently possible to link to their entries so for now I’ve had to remove the links. Apparently they are working to fix things so hopefully we’ll be able to reinstate the links at some point.
On Friday I met with Deven Parker to discuss her Playbills project and the requirements document I sent her before Christmas. We discussed a few issues that had been raised in the feedback on the document and made a plan for the coming weeks, during which I will begin to work with the data and will start developing the online resource.
Other tasks I tackled this week included replacing the data I’d uploaded for the VARICS project last week with a new version I’d been sent, and also making several tweaks to the code and content of the lookup feature. I also changed the language abbreviation ‘Ga’ to ‘Ir’ in the place-names of Armagh content management system and fixed a typo in the Hummell edition on the Burns website that went live before Christmas.
Week Beginning 5th January 2026
My first week back after the Christmas holidays was mostly taken up with travelling to and attending a workshop in Zurich hosted by the ‘Waxing and Waning Words: Lexical Variation and Change in Middle English’ project (https://www.waw-me.uzh.ch/en.html). This project will be producing a Middle English thesaurus comparable to the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) that I was responsible for developing back in 2018, and over the past year or so I’ve been helping out the project’s developer by sharing the BTH code, some sample data, and discussing how it all interoperates.
The workshop was a great opportunity to meet the project team and to work with their developer Tony Harris in person. Working together in person is considerably more effective than communicating by email or even via online video calls and it was hugely productive. We spent at least a day of the day and a half workshop working together and Tony’s knowledge and understanding of the system and its data structures increased massively during this time. We worked with an initial dataset that the project team has created for the semantic domain ‘law’ and by the end of the first day we had created a pathway for importing this data into the thesaurus structure, meaning it could be searched and browsed in the same way as the BTH. We also created links out from the headwords to the Middle English Dictionary. Tony was then able to then apply this workflow to another semantic domain (medicine) and was able to demonstrate a working online resource to the other workshop participants the following day. He should now have everything he needs to process the project’s data an integrate it into the thesaurus as the project proceeds.
It was great to be back in Zurich again, having attended a workshop there some three years previously, but our journey to and from Zurich did not go at all smoothly this time, due to some rather severe weather conditions. There are no direct flights from anywhere in Scotland to Zurich so we had to change flights at Heathrow. Unfortunately due to delays we missed our connecting flights both on the way out (on Tuesday) and the way back (on Thursday), which made for a lengthy and rather stressful journey. This was especially bad on the return journey as our connecting flight was the last flight of the day from Heathrow to Glasgow, meaning we had to stay overnight in London and get an early flight back on Friday morning. This was all pretty exhausting, but we did at least finally get back to Glasgow safely and despite the travel difficulties the workshop was worth it.
I only had time on Monday and Friday afternoon to work as usual this week, and some of Monday was taken up preparing for my trip. However, I did manage to get a few things done. In the run-up to the Christmas holidays I’d been working with the Hansard frequency data and at the start of the holidays I spent some time writing and executing a script to output the data for each year (199 years from 1803 to 2004, with some gaps) as a separate CSV file. I tweaked the data a bit to change the three-character month text to an integer, as this makes it easier to order the data by month (e.g. so ‘apr’ doesn’t come first). It also saves some space. I set the script running overnight and it had completed by the morning. It turns out we only have Commons data and nothing for Lords, with the 199 CSV files taking up 37.6GB (although when zipped this drops to 5GB). I uploaded this to Teams so Marc and Fraser can access it.
On Monday I wrote a further script to export the remaining metadata tables from the Hansard database running on my laptop. These tables contain information about speeches, speakers, parties, roles etc, and are connected through to the frequency data via the speech filename. My scripts exported these tables as CSV files and I added them to Teams too. They should be useful in allowing the frequency data to be limited to a speaker or group of speakers, or a particular political party and such things.
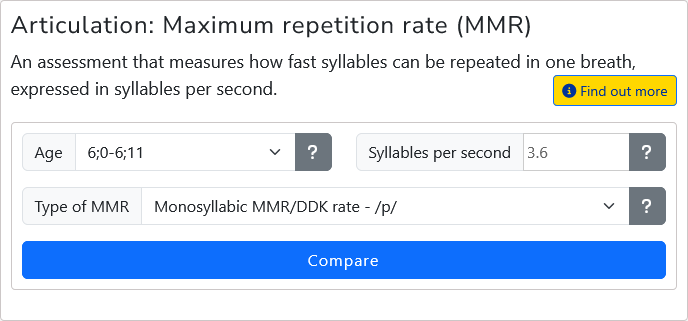
Also on Monday I spent a bit of time working on the VARICS project. Before Christmas I was sent some further data for the lookup feature I’ve developed for the project, this time for maximum repetition rate. It took quite a while to get this working as the new data has a different structure to previous lookup types. Once selected the type then has several subtypes, such as ‘Monosyllabic MMR/DDK rate – /p/’ so I needed to ensure a further selection was added to the interface and also that this was taken into consideration when the data was being queried. The data itself also included several new fields for ‘coefficient of variation’ that also needed to be stored and displayed.
I decided to create a new table to this new data type, populated it with the data from the spreadsheet I’d been sent and created new display and measurement analysis code for the new type. The new display for the speech measure can be seen below:
When I returned to work on Friday afternoon I made some tweaks to the metadata for the Speech Star ‘MRI Modelled Speech Corpus’ (https://www.seeingspeech.ac.uk/speechstar/mri-speech-corpus/) that Eleanor Lawson had asked me to make. I also began to investigate updating the BTH display of lexemes to add in options to order them by date and length of attestation in addition to alphabetically by headword, something we offer through the main Historical Thesaurus and we’d discussed at the workshop. I wrote a script to generate the length of attestation and will hopefully implement the ordering options next week.
I also investigated an issue someone at the workshop spotted with some of the BTH lexemes having start dates later than their end dates. It turns out that there are 197 such lexemes, which I exported as a spreadsheet and sent to Louise Sylvester for checking. Hopefully it’s a simple case of the start and end dates getting accidentally added the wrong way round and a simple switch will sort things.
Week Beginning 1st December 2025
My time this week was divided between several different projects and meetings. I spent quite a bit of time working with Transkribus, ahead of Friday’s Transkribus workshop at which I was speaking about my text extraction experiments with the Edinburgh Gazetteer (https://edinburghgazetteer.glasgow.ac.uk/). Back when I worked on the project with Rhona Brown (almost ten years ago now) we’d attempted to extract the text from the images using OCR but our experiments had been pretty hopeless. I attended a Transkribus event in Edinburgh earlier this year and had done a little bit of work with the Gazetteer in Transkribus then, but hadn’t progressed very far. This week I made considerably more progress, experimenting with a three-column subsection of one page, as you can see below:
Transkribus can identify columns of text by analysing what it calls ‘Fields’ so this is what I asked it to do first, using the ‘Baroness of Blocks’ model. This is something that’s only available with a subscription, but I was able to make use of a free trial. Unfortunately the process was not very successful. It did correctly identify the columns, but split the image up into sections within each column, with some parts of the image entirely missing from the classification (e.g. the top of column 2) in the image below:
I manually corrected this using the interface, as the following image shows:
However, I’m uncertain how I would be able to train the system to automatically and correctly identify such columns for other images – this would require further investigation. The next step was to identify lines within each column, which is accomplished using a ‘Layout’ model. I chose the default ‘Mixed line orientation’ model which was pretty successful in identifying all of the lines in each column. It wasn’t perfect but it was good enough for test purposes, as you can see below:
The third step was to extract the text. For test purposes I wanted to see how the model would work without any training, and I chose the ‘Text Titan I ter’ model. This took several minutes to process, but the results were very encouraging, as the following image demonstrates:
There were some issues, however, such as the large drop-characters at the beginning of sections being omitted, and some words that are legible to humans being incorrect, such as ‘acie’ instead of ‘acre’. The ends of lines in the first column were also missing, so line identification would need to be tweaked. Despite these issues the text is broadly understandable and complete. The poor print quality and the long ‘S’ character were processed successfully and some sections that were very difficult for a human to decipher were processed successfully by the tool. There are still issues to be ironed out with regards to successfully identifying columns of text, and these would need to be addressed before any batch processing of the entire Gazetteer, but it’s looking very promising.
I spent most of Tuesday this week attending the presentations for the new Grade 8 and Grade 7 roles for the post-graduate course in Digital Humanities that is being set up in Information Studies. It was really interesting to hear the presentations and to learn more about what the candidates would bring to the roles. There were some really excellent candidates and it was very useful to hear from them.
Also this week I spent a little time working on the Place-names of Ayrshire project ahead of next week’s launch and engaged in a continuing email conversation about how the data for the interactive map will be gathered and stored for Ophira Gamliel’s Malabar project. We’ve now managed to reach an agreement on how to proceed with this, which is a relief. I also spent some time continuing to make updates to the Place-names of Armagh resource, creating a nice interface for the project website using suggested public domain images and fonts, and adding parishes and baronies to the content management system. The new project website is not yet live, but here’s how the new design currently looks:
I’ll meet with the project team next week to give a run-through of the CMS and working with WordPress, after which they should be in a position to start adding data to the resource. I also managed to spent a little more time working with the data for the Fife place-names project, continuing to rationalise the place-name elements and their connections, but there is still more to do for this.
On Thursday this week I met with Deven Parker to discuss the requirements for an online resource for her Playbills project. We discussed the kinds of search and browse facilities she would like to include and other features such as visualisations and data summaries. Next week I’m going to write up the requirements and share the document with her. Also on Thursday I met with Wendy Anderson and Carole Hough to discuss some potential future updates to the Mapping Metaphor resource. I can’t really go into any details here, but we had a good meeting and will consider the options before meeting again in the New Year to see how this might be taken forward.
Week Beginning 10th November 2025
I continued to work on the new interface for the Dictionaries of the Scots Language this week, ahead of the DSL’s face-to-face meeting on Wednesday at which I gave a demonstration of the interface. There was a lot still to do before the meeting, and I ended up working several hours over the weekend to ensure everything was ready. By Tuesday I’d managed to complete just about everything, although there are still a few formatting issues with some of the ‘history’ pages that I’ll need to tidy up at some point. With the completed interface still only running locally on my laptop the next step was to deploy it to our online test instance of the DSL site, which thankfully only took a couple of hours to complete.
I then spent most of the rest of Tuesday writing and preparing the text of a walkthrough of the new interface for Wednesday’s meeting. Of course, whilst creating this walkthrough I spotted several minor issues with the site and spent some further time addressing those too. I didn’t need to be at the meeting in Edinburgh until the afternoon so in addition to running through my demo a few times on Wednesday morning, I also added a feature to the site’s bibliography page that I’d been meaning to implement for a while. The bibliography page as it currently stands is a bit of a dead end on the site: you search for an author or title and you reach a bibliographical record for a specific work or works. There is nowhere to go from there – no pathway to take you from the record to the entries that cite the work or works. We store this information in the database already, so I figured it would be good to add the links in. I therefore updated the API to ensure a call for a bibliographical record also returned a list of all entries that cite the record, and updated the bibliography page to add in a count of these entries and links through to them. I think this works really well – for example if you search for Irvine Welsh you can now find a list of all SND entries that feature a quote from one of his books. The only downside is that some bibliographical records (especially for DOST) appear in thousands of dictionary entries, meaning thousands of links appear on the bibliography page. I’ll need to think about how to handle this, as currently all links to entries just appear as in-line buttons. We actually store the quoted text in the database so we could also display the specific quotes in the bibliography page if we want. I also still need to update things so that the links through to the entries lead directly to the first matching quote.
My demonstration of the new interface on Wednesday went very well. Everyone was very pleased with how the new site looks and functions and were also very pleased with the new bibliography page. We had a good discussion session about further possible updates, and it’s now over to the DSL team to use the new interface over the next few weeks (or possibly months) and then send on any required updates to me. I still can’t really share any screenshots of the new site at this stage, and it’s likely to be several months before it goes live, assuming the DSL team want to go live with it.
I’ve been suffering from what is most likely sciatica over the past couple of weeks, which has made it quite difficult to work. I’ve generally been unable to leave the house much, although the pain eases off as the day goes on and I’m able to move more freely in the afternoons. I’ve been unable to come into the University during this time, which has meant I’ve had to join some meetings online instead of in-person, and I also had to miss the Arts and Humanities developers coffee and catch-up that we’d scheduled for Tuesday this week. I was able to make it across to Edinburgh on Wednesday as I didn’t have to leave the house until lunchtime and the pain wasn’t as bad by then. Unfortunately the journey through exacerbated things and I was in quite a lot of pain the next day. It was impossible for me to sit at my desk for more than a few minutes at a time and I’m afraid I had to take the day off sick.
I was still in a lot of pain on Friday but I managed to work again, and I spent the day catching up with emails and investigating the Hansard data that I last worked with some seven years ago, as Marc and Fraser have a student who wants to work with it. I also spent a bit of time fixing an old Robert Burns resource that had stopped working. The Jame Currie site (https://jamescurrie.gla.ac.uk/) is not one of mine, but had apparently not worked properly since a server update. I fixed a number of issues with the code and got it working again. I’ll need to see about fully overhauling the site at some point as it contains some very useful research data but has a rather ancient interface. I also found some time to return to the migration of the Place-names of Fife data to the new place-names system, working through the historical form sources. There’s still a lot of work that needs to be done on the data before it can be fully migrated, but I’m slowly making progress.