Category: Historical Thesaurus of English
Week Beginning 12th January 2026
This was my first proper week back at work, having spent most of last week travelling and attending a workshop in Zurich. I spent a bit of time working on the Bilingual Thesaurus of Everyday Life in Medieval England, looking into issues that had cropped up at the workshop. Someone had spotted that the start and end dates for some lexemes appeared to be the wrong way round and last week I discovered there were 197 such cases. I had an ongoing discussion with the project PI Louise Sylvester about this. She sent me a spreadsheet that contained updated data for the thesaurus, with the idea being that we could check the erroneous dates against this. However, the spreadsheet was created for a later project than the BTH and had both a different structure and different data. For example, some categories in the online BTH were not included and many categories in the spreadsheet featured different or larger numbers of lexemes. The dates were in a different format, featuring ‘ante’ and ‘circa’, plus a question mark to denote other uncertainty and a plus to denote continuation. The BTH features none of this – just start and end dates. The spreadsheet also featured no links out to the MED and the AND, only links to the OED. We did wonder whether we should replace the online BTH with the data from the spreadsheet but all of these issues mean this just wouldn’t work. Instead we decided that I would (at some point) write a script to identify lexemes in the spreadsheet that are not in the online BTH and we can see about incorporating them. In the meantime I fixed the 197 lexemes that had their dates the wrong way round.
Also for the BTH this week I implemented an option to order the lexemes in a chosen category alphabetically, by first attested date or length of attestation (within the AN or ME section), where previously all lexemes were ordered alphabetically within each section. This is something that was raised at the workshop, and something I wanted to implement as it’s a useful feature. I’d already included this option in the main HT and parts of the code for it were lurking in the BTH code in an inactive state, although I needed to rework this as the main HT handles dates in a more complex manner. The update required changes to the database, the CSS, the PHP and the JS scripts, but it’s all now live and the site remembers your choice during your session, so if you select ‘length of attestation’ in one category and then navigate to another this is remembered. Below is a screenshot showing a category with the lexemes ordered by length of attestation:
This week I met with Jennifer Smith to discuss the talk we’re giving about Speak For Yersel in Edinburgh in a couple of weeks. We had a good chat and made a plan about writing our respective sections. I then spent about a day preparing the slides and text for my section and sent everything over to Jennifer so she could work on her parts.
Also this week I did a little bit of work for the AND, updating links from AND entries to the DMF, as their site has changed, which broke all our links. I thought I’d found a way to link through to their corresponding entries but unfortunately their URLs now include a session variable that expires after a while, and the URL doesn’t work without a valid session. This means it’s not currently possible to link to their entries so for now I’ve had to remove the links. Apparently they are working to fix things so hopefully we’ll be able to reinstate the links at some point.
On Friday I met with Deven Parker to discuss her Playbills project and the requirements document I sent her before Christmas. We discussed a few issues that had been raised in the feedback on the document and made a plan for the coming weeks, during which I will begin to work with the data and will start developing the online resource.
Other tasks I tackled this week included replacing the data I’d uploaded for the VARICS project last week with a new version I’d been sent, and also making several tweaks to the code and content of the lookup feature. I also changed the language abbreviation ‘Ga’ to ‘Ir’ in the place-names of Armagh content management system and fixed a typo in the Hummell edition on the Burns website that went live before Christmas.
Week Beginning 5th January 2026
My first week back after the Christmas holidays was mostly taken up with travelling to and attending a workshop in Zurich hosted by the ‘Waxing and Waning Words: Lexical Variation and Change in Middle English’ project (https://www.waw-me.uzh.ch/en.html). This project will be producing a Middle English thesaurus comparable to the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) that I was responsible for developing back in 2018, and over the past year or so I’ve been helping out the project’s developer by sharing the BTH code, some sample data, and discussing how it all interoperates.
The workshop was a great opportunity to meet the project team and to work with their developer Tony Harris in person. Working together in person is considerably more effective than communicating by email or even via online video calls and it was hugely productive. We spent at least a day of the day and a half workshop working together and Tony’s knowledge and understanding of the system and its data structures increased massively during this time. We worked with an initial dataset that the project team has created for the semantic domain ‘law’ and by the end of the first day we had created a pathway for importing this data into the thesaurus structure, meaning it could be searched and browsed in the same way as the BTH. We also created links out from the headwords to the Middle English Dictionary. Tony was then able to then apply this workflow to another semantic domain (medicine) and was able to demonstrate a working online resource to the other workshop participants the following day. He should now have everything he needs to process the project’s data an integrate it into the thesaurus as the project proceeds.
It was great to be back in Zurich again, having attended a workshop there some three years previously, but our journey to and from Zurich did not go at all smoothly this time, due to some rather severe weather conditions. There are no direct flights from anywhere in Scotland to Zurich so we had to change flights at Heathrow. Unfortunately due to delays we missed our connecting flights both on the way out (on Tuesday) and the way back (on Thursday), which made for a lengthy and rather stressful journey. This was especially bad on the return journey as our connecting flight was the last flight of the day from Heathrow to Glasgow, meaning we had to stay overnight in London and get an early flight back on Friday morning. This was all pretty exhausting, but we did at least finally get back to Glasgow safely and despite the travel difficulties the workshop was worth it.
I only had time on Monday and Friday afternoon to work as usual this week, and some of Monday was taken up preparing for my trip. However, I did manage to get a few things done. In the run-up to the Christmas holidays I’d been working with the Hansard frequency data and at the start of the holidays I spent some time writing and executing a script to output the data for each year (199 years from 1803 to 2004, with some gaps) as a separate CSV file. I tweaked the data a bit to change the three-character month text to an integer, as this makes it easier to order the data by month (e.g. so ‘apr’ doesn’t come first). It also saves some space. I set the script running overnight and it had completed by the morning. It turns out we only have Commons data and nothing for Lords, with the 199 CSV files taking up 37.6GB (although when zipped this drops to 5GB). I uploaded this to Teams so Marc and Fraser can access it.
On Monday I wrote a further script to export the remaining metadata tables from the Hansard database running on my laptop. These tables contain information about speeches, speakers, parties, roles etc, and are connected through to the frequency data via the speech filename. My scripts exported these tables as CSV files and I added them to Teams too. They should be useful in allowing the frequency data to be limited to a speaker or group of speakers, or a particular political party and such things.
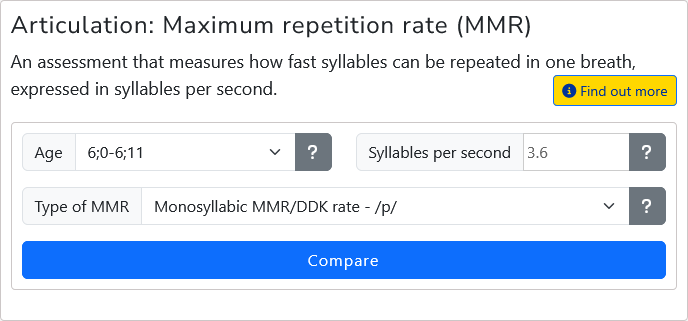
Also on Monday I spent a bit of time working on the VARICS project. Before Christmas I was sent some further data for the lookup feature I’ve developed for the project, this time for maximum repetition rate. It took quite a while to get this working as the new data has a different structure to previous lookup types. Once selected the type then has several subtypes, such as ‘Monosyllabic MMR/DDK rate – /p/’ so I needed to ensure a further selection was added to the interface and also that this was taken into consideration when the data was being queried. The data itself also included several new fields for ‘coefficient of variation’ that also needed to be stored and displayed.
I decided to create a new table to this new data type, populated it with the data from the spreadsheet I’d been sent and created new display and measurement analysis code for the new type. The new display for the speech measure can be seen below:
When I returned to work on Friday afternoon I made some tweaks to the metadata for the Speech Star ‘MRI Modelled Speech Corpus’ (https://www.seeingspeech.ac.uk/speechstar/mri-speech-corpus/) that Eleanor Lawson had asked me to make. I also began to investigate updating the BTH display of lexemes to add in options to order them by date and length of attestation in addition to alphabetically by headword, something we offer through the main Historical Thesaurus and we’d discussed at the workshop. I wrote a script to generate the length of attestation and will hopefully implement the ordering options next week.
I also investigated an issue someone at the workshop spotted with some of the BTH lexemes having start dates later than their end dates. It turns out that there are 197 such lexemes, which I exported as a spreadsheet and sent to Louise Sylvester for checking. Hopefully it’s a simple case of the start and end dates getting accidentally added the wrong way round and a simple switch will sort things.
Week Beginning 8th December 2025
My time this week was mostly divided between two projects: The Place-names of the Coalfield Communities (Ayrshire) and the Eighteenth Century Playbills project. We launched the interactive map of Ayrshire place-names during an online event on Wednesday this week and there were a lot of last-minute updates that I needed to implement leading up to this. This included replacing a lot of placeholder text with actual text, both on the map and the project website more generally and fixing a number of issues with the data. It turned out that there were almost 250 place-names in the system that had a grid reference that was used by another place-name. This meant that the map markers were sitting on top of each other and unless the data was filtered it was impossible to tell that multiple markers existed at the point. To rectify this I wrote a little script that identified the places that shared a grid reference and all places after the first had their longitude updated to move them slightly east of the original location, ensuring the markers did not overlap. This approach has worked pretty well, although the researchers do still need to properly investigate the duplicates as there are some that are genuine duplicates and should probably be removed.
There was also a slightly strange issue with the CMS, whereby making updates to a specific place-name element was getting blocked by the WordPress plugin Wordfence that runs on the domain. What was especially strange was that the update was getting blocked in Chrome-based browsers but was completing successfully in Firefox, even though the issue was server-side and the posted data should have been identical in both browsers. It was the description field that was getting blocked, and it looked like this was due to the element having a fairly long description, as when I replaced it with a shorter text the update was fine. There was nothing in the contents of the original description that would have caused issues – just a few simple HTML tags. In the end I just had to add an exception to Wordfence to stop it blocking the upload page, and this worked. It’s not like Wordfence should really be processing data added via the non-Wordpress, password protected CMS anyway.
I also needed to fix element languages in the elements glossary, as several of these were appearing as beginning with ‘other’ in the alphabetical list, even though they clearly shouldn’t have been. This was because I created a new ‘element sort order’ field in the database to be used for the alphabetical list and generated the data for it using a script. But what I forgot to do was update the CMS pages where elements are added or edited to ensure this field subsequently gets populated. This meant any elements added after I ran the script to generate the field didn’t have data in the field and so the elements were appearing as ‘other’. I fixed this for the Ayrshire site and also ensured the fix was in place for the other place-names resources too.
Some further tweaks to the elements were required as there were seven different ‘?’ elements (used where an element is unknown) and I merged these into one record. I also ensured that element certainty in the ‘more information’ view of place-name elements was appearing. This should have been visible but wasn’t showing up in any of the place-names resources. A quick tweak of the various APIs got this working across all of the place-names resources.
With all of these updates in place I went live with the map on Wednesday morning, creating a cached version of the full map view data to ensure that the initial map loads speedily. I also spotted some issues where place-names hadn’t been assigned a classification code, resulting in a blank item getting added to the map legend, and I fixed these.
The online launch of the map (now available at https://ayr-placenames.glasgow.ac.uk/map/) went very well and everyone seemed happy with the map, its data and its potential uses. I’d say the session was a great success.
I spent most of the remainder of the week writing a requirements document for the front-end for Deven Parker’s Playbills project. I had hoped to begin work on this earlier in the week, but there was rather more to do before the project launch than I was expecting. There is a lot to consider for the playbills project in terms of how to process and store the data and present everything online, and by the end of the week I was probably only about half-way through writing the requirements document. I’m hopeful that I’ll be able to complete it next week, though.
Also this week I updated the facility to save an SVG version of the Historical Thesaurus timeline visualisation to make the process fully JavaScript based. Previously the SVG was exported for download by posting the XML data to a PHP script, which then triggered the download. The purely JavaScript way means that no data needs to be posted and echoed out by PHP, which is more secure. I also had some discussions with the Stirling IT people about bot traffic on the Books and Borrowers site, which is beginning to cause issues. I talked about our recent experiences with the Emblems site and shared the htaccess script Luca created to sort out that issue. Hopefully this will help. I also received a request from Garrick Allen to provide some text for his latest research proposal, and although I began this on Friday afternoon (when the request came in) I didn’t quite manage to finish it. I’ll get this sorted next week.
Week Beginning 17th November 2025
After spending a pretty intensive few weeks working on the new interface for the Dictionaries of the Scots Language ahead of last week’s in-person meeting, this week I was able to return to other projects that I’d had to put to one side recently. I am still unfortunately suffering from a rather bad bout of sciatica, which is now in its third week and is making it hard to work, especially in the mornings. It has also unfortunately prevented me from travelling to the University, which meant I had to rearrange a couple of in-person meetings this week. Despite all of this I’ve still managed to get quite a lot done this week.
I spent a lot of my time this week working on the migration of the place-names of Fife data, which I’d started to look into again last Friday. I hadn’t had any time to work on this since September and it was good to get back into it. I’m migrating the Fife data, which I originally extracted from a Word file into a relational database structure way back in 2016 to the same structure that I created for other place-names projects such as Berwickshire and Iona. As the Fife data is very messy there’s much work to be done to get it ready.
This week I managed to complete work on the historical forms. There are more than 23,000 historical forms in the data, and for Fife the sources of these forms are stored as a field in the historical form table, meaning there are more than 23,000 sources. For the other projects an individual source is stored in a separate ‘sources’ table only once, and then is connected to all relevant historical forms via a joining table that also stores the specific reference for the form (e.g. a page number).
What I needed to do for the Fife data was to extract the unique sources, separate out the reference data (which was stored as part of the same field), insert new sources once into the ‘sources’ table and add in references to this source for each historical form where the source appears. Thankfully there were some patterns to the source data, plus the same sources kept cropping up for many of the historical forms. For example, the source name was italicised in more than 11,500 historical form records, which made it easy to split up the source name from the reference and process these sources.
Of the remainder there were a number of major sources, such as ‘OS 6 inch 1st edn’, found in almost 2,200 historical form records. I was able to process sweeps of the data that ticked off hundreds or thousands of historical forms at a time, which then left me with the awkward records that needed more manual intervention. Even in such cases I was able to automate the process to a certain extent by first finding where the source name ended and the reference began, and then for each historical form that featured the source splitting the field at this point and storing the source and the reference. I manage to sort out all 23,000+ historical forms this week using various methods, resulting in less than 500 unique sources being stored. This is of course still just a first draft and there will almost certainly be some duplicates due to different spellings and such things, but the source data is now in the right format and is clean enough to be managed through the place-names CMS system, once I get round to setting it up for this project.
I also began work on the final data migration I’ll need to tackle for the Fife data: the place-name elements. As with the source data, these are not stored in an especially relational way. In the more modern place-names projects each element is stored once has an associated language that is stored once. When elements appear in a place-name they are then associated by means of a joining table that stores a reference to the element and the place-name, and information about how the element appears within the place-name, such as its position and how it is connected to a subsequent element. In Fife this is all just stored in one table, meaning there are almost 6,500 elements. I began cleaning this data up a bit this week, as I’d spotted some issues, such as elements being stored without a language due to the data from the original Word file not being processed successfully. I’ll continue with this next week, if I have the time.
Also this week I met with Ophira and Renu to discuss the structure of the spreadsheet that I created to store details about the places that will appear on the map for Ophira’s HiMuJe Malaber project. This should have been an in-person meeting but as I am still unable to leave the house much we had the meeting online instead. We went through the spreadsheet in detail and several structural changes were proposed. After the meeting I then spent some time making the updates and ensuring these were logged in the accompanying data dictionary.
Also this week I had a lengthy email conversation with Andrew McHugh, Luca Guariento and others about hosting the online resource for one of Garrick Allen’s projects. This is currently hosted elsewhere but Garrick would like it to come to Glasgow. There was a lot to discuss about this request as the resource uses technologies we don’t otherwise support at Glasgow, but by the end of the week we’d reached a decision about how and where the resource should be hosted, and Luca has agreed to oversee the process.
I also found a bit of time this week to finally swap the live Historical Thesaurus website with the new version I created earlier this year that uses a new, unified API, unlike the mess of scripts that were cobbled together over a decade or so of development that previously powered the site. This is a major update to the resource’s back-end but includes no changes whatsoever to the front-end, so all of the work that went into it should be invisible. But it will make it much easier to manage the resource in future as all data access now passes through one script.
I had an in-person meeting planned with Deven Parker this week to discuss her playbills project, but I was unable to travel into the University and instead we had an email conversation. Deven is just about at the stage for me to begin creating an online resource for the data, and she shared with me the YAML files that had been generated by the AI ‘reading’ the playbill images and extracting and formatting the data. My first task was to identify which of the playbills had been classified as ‘melodrama’ as it is these that Deven wants to initially focus on. Deven needed some help in creating a Python script that could export a list of matching YAML files, and this was a good opportunity for me to learn a bit of Python, as this is the kind of activity I’d normally just write a PHP script for. I managed instead to write a Python script that did was Deven needed, and we had a lengthy email conversation about the data, the project and the next steps. I’ll hopefully be well enough to meet her in person soon to define some requirements for the resource she’d like me to build soon.
Week Beginning 3rd November 2025
I spent pretty much the entirety of this week continuing to develop the new interface for the Dictionaries of the Scots Language website, applying the Bootstrap-based mock-up I’d created many months ago to an instance of the actual DSL website running on my laptop. I can’t really go into too much detail about the new interface or provide any screenshots at this stage, but it’s been a pretty intensive process as every aspect of the old interface needs to be changed and various parts of it need to be integrated with WordPress, for example making widgets and ensuring the new layout works with different templates.
I managed to complete the bulk of the work this week (although this did include working several hours over the weekend too), in preparation for next week’s face-to-face DSL team meeting. This included the search results pages, the advanced search page, the dictionary entry page and the bibliography page. This may not seem like a very long list, but there was a huge amount of work to do on each of these pages, such as implementing the site panel for the entry page that features the dictionary browser, the search results browser and a new ‘entry log’ that keeps a record of entries the user has looked at during their session. I reckon the new interface is looks really good, and is a massive improvement on the live site, although there will inevitably be many further changes to be made before anything goes live.
I still need to complete the new top-level ‘About’ page, which acts as a large menu page, plus ensure that all regular WordPress pages work with the new interface and include the quick search. I’m hoping to finish these things off and then apply the interface to our online test instance of the site ahead of Wednesday’s meeting next week.
Also this week I spent a bit more time preparing for a talk about Speak For Yersel and Jennifer Smith and I were scheduled to give at the University of Edinburgh the week after next. However, later in the week we heard from the organisers that the University will be on strike when our talk is scheduled and we therefore reached a decision to cancel. It’s possible that we’ll be able to reschedule, as we are not directly involved in the strike action, but we’ll just need to see.
Also this week I created an initial version of a website for Henry Ivry’s project and contacted researcher Jenny Buckley with some further information about the processing of historical newspapers that might be of use for her project. I also made a small update to the Speech Star resource and had an email conversation with Eleanor Lawson about access restrictions for the resources data.
I participated in an online meeting regarding sharing the SCOSYA data with the Mozilla Foundation this week, and I also had a meeting with Pauline Mackay and Cleo O’Callaghan Yeoman to discuss a new phase for the Interactive Map of Burns Suppers. I subsequently spent a bit of time reviewing some materials for the site. Finally, I exported some data from the Historical Thesaurus that we’re going to share with another project.
Week Beginning 2nd June 2025
I made the Iona place-names map resource live this week, in preparation for the official launch on Monday next week. After working on the project on and off for several years it’s great to get the resource out there. It can be accessed here: https://iona-placenames.glasgow.ac.uk/map/.
I spent a lot of my time this week continuing with the development of the versioning system for the Books and Borrowing project. Due to other commitments I didn’t manage to work on this task last week, having completed the updates to the scripts for generating the cached data the week before, so it was good to be able to return to this task and make a bit of progress. This week I focussed on updates to the API, which is a pretty major task as every single database call in more than 5000 lines of code needs to be updated. Before I did so I also had to consider how the user’s selected data version would be passed to the API. Appending it to the end of the existing set of parameters would be messy, as each endpoint would then potentially have the version passed through a different parameter. Instead I decided to that the version should appear at the very start of each endpoint call, before the file type selection. So for example, ‘/api/v2/1/json/libraries’ will retrieve all ‘version 1’ data for the ‘libraries’ endpoint as a JSON file while ‘/api/v2/2/json/libraries’ will retrieve all ‘version 2’ (and version 1) data. In order to ensure older calls that don’t feature the version number continue to work, I set the API to use the ID of the most recent live version of the data if the version number is omitted. Also, the API checks to ensure that any version number passed does actually correspond to a version of the data that is actually live in the system, so the API will never publish data that is still in development.
With this update to the API in place I then needed to work through every database query in every endpoint in order to add in the version limit. In some endpoints this was pretty straightforward to do, but other ones did get rather complicated, involving cached data in new database tables or specific versions of cached JSON files. I didn’t manage to complete the update to the API by the end of the week, but I’m hopeful I’ll be able to do so next week, at which point I aim to add a new version of the API to the live site, in preparation for redeveloping the front-end to work with the versioning system.
On Thursday this week we had the interviews for Ophira Gamliel’s project, and this took up more than half of the day. The interviews all went smoothly and we had a good discussion about potential candidates afterwards.
Also this week I had a chat with Geert, the editor of the Anglo-Norman Dictionary, about further updates to the site. We’re intending to add in a part of speech option to the advanced search and we spent some time discussing how this might function. I also gave him so advice on long-term digital preservation, helped him set up a new ‘phase’ and fixed an issue when adding lead editor initials to entries through the dictionary management system.
I also gave some advice to Tony Harris, who is developing a thesaurus system based on my code for the Bilingual Thesaurus, and fixed a couple of issues that Marc had spotted with the unified API version of the Historical Thesaurus that I worked on in April. Marc had spotted that some information was missing from the ‘recommended’ category section in the search results. The blank recommended category information was caused by the API correctly returning an empty subcat array for categories that don’t have subcats. Unfortunately the front-end code was checking for the presence of this array when deciding whether the recommended category was a sub or main category, and as the array was present (but empty) for maincats it was treating them as subcats and not displaying the correct details. It took a while to identify the cause of the problem but once I’d done so it was very easy to fix. The second issue that Marc spotted was a URL encoding issue, with both slashes and spaces causing problems. This was something I managed to sort relatively quickly.
Week Beginning 31st March 2025
My main task for this week was to complete my work on the new API for the Historical Thesaurus. As I mentioned last week, I’ve been working on a new version of the HT website that fully separates out all data queries into a single API, which the front-end then connects to in order to pull in the necessary data. The current version of the website was developed over many years and data queries were found all over the place – embedded in the front-end scripts and located in AJAX calls, with an additional, initial stab at an API used for the lexical sparklines. Over time it all became something of a tangled mess.
The new API brings all data queries together in one place, offering options to access the data as either JSON or CSV files. This is a much neater solution that is easier to maintain. It also makes updating (or in future entirely replacing) the front-end much simpler as it no longer includes database calls and only needs to include minimal data processing.
The API endpoints I’ve created cover every data query that is required to power the front-end, and they feature descriptions, a list of the arguments that can be passed to them and examples. As mentioned previously, the data can be accessed as JSON (used by the front-end) or CSV. It’s possible that the structure of the CSV files could be improved – it’s difficult to represent multi-dimensional data in a two-dimensional spreadsheet – so depending on feedback from Marc and Fraser I might need to do some further work on this aspect.
In addition to developing the API I also created a new version of the front-end that connects to it. In terms of visuals and functionality this is identical to the live site, but every script has been updated to funnel all data queries to the new API. I’ve tested it out pretty extensively and all seems to be working perfectly, so that’s my redevelopment of the back end of the Historical Thesaurus website completed. I just need Marc and Fraser to test out my test site, and once I have their approval I’ll replace the live site with the new version.
Also on my long-term ‘to-do’ list is redeveloping the front-end to migrate the interface to Bootstrap, as I did for the Bilingual Thesaurus (https://thesaurus.ac.uk/bth). This will be a pretty major undertaking, as many of the features of the current site (e.g. the timeline popup) use the jQuery UI framework and this would all need to be replaced with Bootstrap equivalents. My plan at this stage will be to replicate the current HT interface in Bootstrap, but we might want to consider a larger overhaul of the interface. Either way it will likely be a while before I am able to devote any time to this.
This week I also published the new ‘cognate reference’ search facility that I’d created for the Anglo-Norman Dictionary, which you can find in the corresponding tab found on the search page: https://anglo-norman.net/search/. This allows you to search for forms found in the cognate dictionaries, so for example finding all AND entries that reference OED words ending in ‘ment’: https://anglo-norman.net/search/cogref/*ment/OED. All seems to be working perfectly and hopefully this will be a useful addition to the website.
Also this week I made some minor but hopefully very helpful tweaks to the interface for the DSL website on our test server, ahead of the launch of the new data which is scheduled to take place the week after next. I updated the page width on narrow screens so that the pages are now wider throughout the site, meaning there is less wasted space down either side of the page. I also updated the site buttons to make them inline-block rather than inline, with a 5px margin at the bottom. This means buttons don’t get split over multiple lines and don’t overlap when there are multiple lines of buttons on narrow screens. I also took the opportunity to update the ‘fixed’ header that appears as you scroll down the entry page. This now takes up with whole width of the browser (at all screen dimensions), which gives more space and looks better. These updates are currently only available on our test version of the site, but will go live along with the major update when it happens in a couple of weeks.
I also had a chat with the Books and Borrowing people about new data that is to be added to the resource. It’s not going to be as simple as just allowing researchers to add new data to the CMS, as Katie and Matt want to add a versioning system to the data in order to ensure that it’s possible to search and reference only the data that was published during the course of the project, as well as searching and referencing all data including subsequent updates. This is going to need some careful consideration as it will likely require changes to the database, the CMS, the API, the Solr indexes and the front-end, and of involvement with the project officially ended several months ago.
Finally this week I made some further updates to the new ‘lookup’ feature I’ve developed for the VARICS project. I updated the lookup page to replace the short definitions with new ones that had bene sent to me, and to remove the measures that the team no longer require. I also added a yellow ‘Find out more’ button to the short description that appears above the form when you press on a measure. Pressing on this takes you to the relevant longer definition. This currently opens in a new tab so the user doesn’t lose the form. I then added the longer definitions to a WordPress page I created, with each definition appearing in a box that has a hidden ID, ensuring that when the ‘find out more’ button is pressed the relevant section of the page loads. I also created a WordPress page for the ‘How to’ information that I’d been sent, which features text and infographics for each ‘how to’, again with each one in a separate box. I made the images appear as links that when pressed on load the full-size versions, as some of the text can be somewhat indistinct in the in-page version.
I’ll be on holiday for most of next week, but will still be working for some of the week and there will be an update as normal after that.
Week Beginning 24th March 2025
I’d received a new batch of data outputted from the editing system used by the Dictionaries of the Scots Language on Friday, and on Monday I processed this, which involved importing the data into the database structure used by the website, generating the data necessary for the search facilities and then outputting all of the data in a format that would then be ingested into the Solr search system. All went pretty smoothly, and after testing everything out locally I uploaded everything to the server. I don’t have direct access to update the Solr cores on the server, so I had to wait until our IT people had the time to run the necessary commands, which they did on Wednesday morning. A few subsequent tests show that all is working as it should, and we’re just about ready to replace the live site with the version we’ve been working on for more than 18 months now.
I also made a couple of further tweaks to the system, such as ensuring the new ‘TypeC’ attribute connects to the correct update statement and dynamically populates the ‘About’ section of the relevant entries. Later in the week the editor Ann got in touch to say that the bibliography search (or more specifically the dropdown list of predictive search options) was running very slowly so I investigated this. I added in some new indexes to the database and this has increased the speed considerably. Rather strangely, the live site doesn’t have these indexes and the queries appear to be exactly the same so I’m not sure why our test site is much slower – the databases are running on the same server. However, the indexes will make things more efficient so it’s good that this was spotted.
Also this week I responded to some queries from the Anglo-Norman Dictionary about our links to the DEAF site from some entries. Unfortunately it looks like their lemma-based URLs are ignoring accents, which means some of our links are leading to the wrong page on their site. For example, the DEAF link on this page: https://anglo-norman.net/entry/herit%C3%A9 leads to this page: https://deaf.hadw-bw.de/lemme/erit%C3%A9 which unfortunately displays the same content as this page: https://deaf.hadw-bw.de/lemme/erite even though ‘erite’ and ‘erité’ are different words. The only way to reach the correct page is to perform a search for it and select it from the left-hand column: https://deaf.hadw-bw.de/?type=shortarticle&id=38050#erit%C3%A9 but we can’t use such a link in our XML as it would require us to know the ID of every lemma we link to. It’s not ideal for a French language website to not be able to differentiate accented and non-accented characters, but that appears to be what’s happening. Strangely, other links on the DEAF site do differentiate accented characters. For example: https://deaf.hadw-bw.de/fiches/erit%C3%A9 and https://deaf.hadw-bw.de/fiches/erite display different content. It’s just their ‘lemme’ links that don’t work properly.
In addition, I also added a new language to the AND system this week. We now have ‘Scots’ listed and selectable in the XML, and whenever this language is added to entries the search facilities on the website will be automatically updated to enable the language to be searched for. In fact we currently have two entries that have been updated to include Scots at the time of writing: https://anglo-norman.net/search/language/14/null/
On Wednesday this week we had new broadband fitted at our house, and it took a couple of hours to get everything all working with the new system. And on Friday afternoon I attended an event organised by the ‘Realities and Immersion Glasgow’ group at the ARC. This group are looking at virtual / augmented / extended reality systems and their potential use across the university and beyond. It was very interesting to try out several of their headsets and see the work that’s going on in this area, and I’m glad I went along.
I spent most of the rest of the week continuing to develop a new, unified API for the Historical Thesaurus website. I managed to complete work on the search facilities this week, so that’s the bulk of the API sorted now. There are still several visualisations that need their data queries to be plugged in, plus I need to ensure the CSV output works correctly, but I’m hoping I’ll be able to complete work on this next week, depending on what other work needs to be done.
Week Beginning 24th February 2025
On Monday this week I attended a ‘getting started with Transkribus’ workshop held at the University of Edinburgh. This was a really great opportunity to learn more about the Transkribus tool and to be guided through the initial stages of using it. I had somewhat naively thought that it would be possible to just upload a digitised image to the tool and it would then be able to extract and format the text with a high degree of accuracy, but in reality much more manual intervention is required before Transkribus can work effectively. Training the tool on your data is absolutely vital, and this means uploading sample images, identifying lines of text (which can be done automatically but may need manual tweaking) and then transcribing the text found on each line using Transkribus’s web-based text editor. Text can also be tagged using this facility, such as noting headings, or identifying proper names. The leader of the session suggested that around 15,000 words of text should be manually transcribed in order for the tool to be well trained, which would take a considerable amount of time and effort.
I wanted to see whether Transkribus could extract the text from the Edinburgh Gazetteer (https://edinburghgazetteer.glasgow.ac.uk/the-gazetteer/) and the first stage of this would be for the tool to recognised that each page is divided into four columns, many with a full-width heading at the top. A ‘layout’ model would need to be run on the pages in order to automatically identify the columns. There are a couple of existing newspaper layout models available but unfortunately when I ran my test image through them neither managed to divide the page, and the entire page was simply identified as ‘Region 1’, meaning all identified lines ran across all four columns. Any human looking at the image would be able to ascertain immediately that it’s four columns of text in so I was a bit disappointed that Transkribus wasn’t able to do the same. I spoke to the leader of the workshop, who has successfully used Transkribus on another historical newspaper and he suggested that I’d have to train Transkribus on this specific newspaper and that in order to do so I’d need to use a ‘Field model’. It’s not entirely clear to me how a ‘Field’ differs from a ‘Layout’ model, but unfortunately it’s not possible to create a field model with the free Transkribus account – you instead need to subscribe to a ‘Scholar’ account at €20 a month, something I didn’t want to do as I was just experimenting at the workshop, so I reached something of a dead end. Having said that it was still very useful to experiment with Transkribus in a workshop setting with an expert on hand and I will continue these experiments when I have more time available. However, I do wonder how more general AI tools might cope with the same materials and whether they might be quicker to use. It’s definitely something that would be worth exploring further.
For the rest of the week I worked on several different projects. I spent some time refamiliarising myself with the structure of the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) as a developer who will be working with the structure for a new project got in touch with questions about it. I wrote a data description document that describes every table and column in the database, and also contains the highest ID in each table used for BTH. There are several columns that are only present as references to the original spreadsheet and are not used by the online resource, and I’ve made a note of these. Whilst working on this I also spotted an issue with the display of languages in the advanced search. These were not displaying any content and it turns out that this was because one of the referenced column names was ‘grouping’, which is a reserved word in MySQL. While the queries worked on our old server, the new server is more strict about such things and the queries failed to run on it. Having spotted this it was thankfully quick to fix – surrounding the column name with backticks (`grouping`) in the queries got things working again.
I also returned to working on the Books and Borrowing project for a few hours this week in order to update the links we have in our system to books held at St Andrews University library. The library has recently changed their online system, which has broken all existing links to records in the system. Thankfully they have a huge spreadsheet featuring the old identifiers and the corresponding new ones and I was able to write a little script that would identify the St Andrews book holding records in our system and update their links. Of the 7560 active St Andrews book holding records in our system 1666 have URLs and my script successfully updated 1662 of these. The remaining four have issues that will need to be looked at separately, and I’ve let Katie and Matt know about these.
I met briefly with Alan Riach this week to discuss the website I created for him last week. He gave me a further CD featuring a recording he wanted me to host and I was able to extract the recording and update the website to add this in. I also joined my fellow College of Arts and Humanities developers for a coffee and a catch-up this week, and it was really great to chat with them all again. Hopefully we’ll meet up again soon.
On Thursday this week I also had a meeting with Rhona Brown, Amy Wilcockson and Clare Thompson from the Mitchell Library to discuss an online exhibition for the Robert Fergusson website (https://robert-fergusson.glasgow.ac.uk/). There was a physical exhibition of materials at the Mitchell last year and we’re going to be bringing these together online in the next few months. It was good to meet everyone in person and hopefully I’ll be able to help them create an exciting online resource based on the materials.
Also this week I managed to fix the issue with capital letters not working in the ‘jump to’ option in the ‘browse’ facility of the Anglo-Norman Dictionary. You can now enter text and it will find matching entries whether they have capitals or not. E.g. enter ‘abc’ (or ‘ABC’) into the ‘jump to’ box. Brackets are also not an issue, e.g. type in ‘xilo’ and you’ll jump to ‘[xiloaloe]’. The only thing to bear in mind is that the browse is accent sensitive. It has to be as we have entries with headwords that are identical other than for accents. So for example entering ‘acel’ will jump to ‘acelément’ but typing in ‘acele’ will find nothing. However, ‘acelé’ will work. Updating this would be a major undertaking so hopefully it’s not too big a deal – it’s been like this since the new site launched, after all. I also applied the updated I’d made last week to the Iona map interface to all of the other place-names projects.
The remainder of my week was spent going through the feedback I’d been sent from testing of the new data for the Dictionaries of the Scots Language. This included fixing an issue when conducting a search featuring an apostrophe in iOS using the Safari browser. This was adding an a curly apostrophe which then didn’t work with our data. I updated the code to ensure such apostrophes are switched for regular ones when submitted, but when working on this I noted that there are some occurrences of curly apostrophes in the dictionary’s XML files. These characters are treated as entirely different from regular apostrophes and will not be found in a search that contains a regular apostrophe. This led to some discussions with the team about the use of such characters in the data. I also updated the error messages that are displayed when invalid dates are entered in the quotation date filter and spent a long time working through the sparkline data generation code to ensure certain edge cases are resolved.
It’s been a long time since I wrote the sparkline code (I began in June 2023!) and it took some time to refamiliarize myself with the it, but I managed to sort all of the issues you had been reported. Unfortunately these fixes needed to be made to the code that generates the sparkline data that then forms part of the Solr index so no updates were initially available on our test server. Instead I ran many tests on my laptop, both before regenerating the Solr data by targeting specific entries and also through a test instance of Solr and the DSL site running on my laptop after regenerating the entire dataset and as far as I can tell all is working without any unintended consequences being introduced. I then asked our IT people to update the online Solr cores and this was completed by the end of the week.
I also tweaked the display of the sparkline dates in the search results on narrow screens. I’ve updated the layout so that the sparkline text and the sparkline are treated as one single block element. If the page is too narrow for both this and the entry title to all fit on one line then the sparkline and its text drops down to a new line rather than different sections being split over different lines. I also updated the CSV output to remove the search result snippets from them and had a chat about the tagging of certain bibliography entries in the data.
Week Beginning 10th February 2025
I divided my time between many different projects this week. For the Anglo-Norman Dictionary I made a few further tweaks to the new cognate references section that we went live with last week, and I also received a new batch of several hundred new or reworked entries that are to be added to the dictionary, which I’ll process next week. For the Dictionaries of the Scots Language I had an email conversation with editor Ann Ferguson about the structure of URLs and also gave some consideration to the bibliography search, based on feedback I received towards the end of the week. I’ll continue to work on this next week.
I also found a bit of time this week to begin work on a new version of the Historical Thesaurus website. The current website’s backend is a bit of a mess, as it was cobbled together over many years as new features were added. What I’ve been meaning to do for a while now was to rework this in order to extract all data querying and processing code from the front-end, separate it out and develop a single, unified API for the site, an approach I’ve taken with all of the large projects I’ve been involved with for many years now. This is going to be a rather large task, but I made a start this week: I set up a new version of the website and began the process of creating the API. So far I’ve only got the ‘random category’ feature on the homepage working with the new API, but I’ll continue working away at this as time allows until it’s all done. There won’t be any change to the front-end (although I’m also separately considering a Bootstrap-based refresh of the interface), but the update will leave the data querying side of things in much better shape for the future.
For the VARICS project I continued to work on the new look-up feature. Following last week’s traffic light experiments the team requested a more simple approach for the traffic lights, so I created new images featuring a subtle gradient and a white border, as you can see below:
I also added in a new ‘Try again’ button that would reload the form, which was subsequently renamed ‘Start again’. The team prefer this simpler approach so it looks like this is what we’ll be going with. I now need to wait until further data is sent to me before I continue to develop the feature.
For the place-names projects, I spent some time investigating an issue with the advanced search in the new map interface. An element language search was not working unless a specific element was also selected. For example, a search for all place-names containing Old English elements wouldn’t run, but selecting Old English and then selecting the element ‘tūn (OE)’ worked perfectly. It took a while to track down the issue, but thankfully once identified fixing it was trivial: there was a typo in the code for the API. The system was already set up to allow a search for element language without specifying an element, but in such circumstances the code failed to run because of the typo. I’ve fixed this now on all of the place-names sites. I also fixed a strange issue with the advanced search pop-up disappearing when parishes towards the end of the list were selected. This issue was only occurring in Chrome and not in Firefox (my default browser) and an update to the stylesheet for the map pop-up thankfully fixed the issue.
I also participated in an online meeting with the Iona project team on Wednesday this week where we discussed some of the map-related issues that had been brought up at the advisory board meeting and how (or if) we should address these. I ended up with a list of updates that I’ll need to make to the interface, another thing I’m hoping to tackle next week.
Also this week I had a brief in-person meeting with Joanna Kopaczyk and her project RA Pia Lehecka to discuss Joanna’s new DOST digitisation project. It was good to meet the other members of the team and I’m looking forward to working for the project over the next few months.
I also met with Alan Riach in Scottish Literature this week. Jean Anderson had contacted me last week to put me in touch with Alan, who was wanting some help to publish some old radio broadcasts that were previously available on one of our old servers that has since been decommissioned. Alan managed to find some audio CDs containing the recordings and I met with him to collect them, together with some additional recordings and a few DVDs. I spent some time towards the end of the week extracting the audio and video data from this media and creating a simple website where the files and accompanying transcripts will be accessible to students. I haven’t quite finished this task yet, but should have an initial version completed early next week. The resource will be password protected and only available to students and staff, as there may be licensing issues relating to the recordings – for example relating to incidental music used during the recordings.