Week Beginning 19th January 2026

I worked on many different projects this week, but the one I spent the most time on was the Dictionaries of the Scots Language.  I’ve not done much work for the DSL since the intensive period I spent developing the new website interface and deploying it on our test server ahead of the face-to-face meeting in mid-November.  I had a list of further updates I needed to make following on from this meeting, but I needed to work on other projects since then and hadn’t got around to it.  I’d also received a number of emails about changes to the presentation of entries reflecting the structural changes to the entry XML that I’d put to one side.

On Wednesday I had an online call scheduled with the DSL team to discuss the new front-end and it seemed like a good opportunity to get back to grips with all of my outstanding DSL tasks.  This mainly involved making updates to the XSLT on our test server to tweak the layout of various items in the new entry XML structure, such as adding commas between tags when they are rendered, ensuring certain tags or attributes that weren’t getting rendered before appeared in the generated HTML, updating the styles of certain elements like the content warning labels, fixing a few bugs such as the ‘sticky’ heading not displaying in certain circumstances.  There were at least 20 such items that needed investigating, fixing and testing, so this took quite some time to work through, but I managed to complete it all during the course of the week.

The meeting itself was very useful and as always it was good to catch up with some of the other DSL team members.  There’s going to be a big push towards getting the new website interface ready for publication this year, and I’m obviously going to be involved in this process.  I already have a number of items I need to sort out with the new interface and I’ll try and get started on these over the coming weeks.

I also spent a bit of time this week working for the Anglo-Norman Dictionary, investigating a strange occurrence with the publication of updates to entries, which turned out to be a user rather than a system issue, reinstating the links out from entries to the DMF dictionary, as their website is now properly back online again, and tweaking the wording of the quick search and ‘jump to entry’ text throughout the site.

I also did small amounts of work for several other projects, such as updating the licensing statements across the Seeing Speech and Star sites, fixing an issue with the ‘download song’ facilities on the Editing Robert Burns site, sorting an issue with the HiMuJe Malabar site, submitting my expenses from the Zurich workshop, exporting some SCOSYA data for Jennifer Smith, helping to sort out an issue with the Helsinki Corpus, and having a conversation with Clara Cohen about a new proposal she’s putting together.  I also made some further updates to the VARICS look-up system, adding in some introductory text, some further references, and reworking the measurement processing so that when a red or amber result is given new textual sections about what this means and what the next steps should be appear underneath in collapsible accordion sections.

Also this week I had a meeting with the Burns Supper Map team to discuss the data that is now coming in and how and when I should start working on a new interactive map to visualise it.  I also put in a request for a new subdomain for the project that was set up by the end of the week.  Next week I’ll probably write a brief specification document for the front-end.

My final project of the week was the Place-names of Armagh project, for which I started working with some existing place-name data for the area.  There are around 230 place-names and several thousand historical forms and I spent quite some time researching how the data was structured and how it might be mapped onto the Glasgow place-names system.  This included analysing the geospatial data, including shapefiles for Townlands and what I though was Parishes (but actually turned out to be the same as for Townlands).  I had hoped to be able to import the data by the end of the week, but my analysis of the data raised a lot of questions that still need to be addressed, and I’ll need to continue with this next week.

Week Beginning 12th January 2026

This was my first proper week back at work, having spent most of last week travelling and attending a workshop in Zurich.  I spent a bit of time working on the Bilingual Thesaurus of Everyday Life in Medieval England, looking into issues that had cropped up at the workshop.  Someone had spotted that the start and end dates for some lexemes appeared to be the wrong way round and last week I discovered there were 197 such cases.  I had an ongoing discussion with the project PI Louise Sylvester about this.  She sent me a spreadsheet that contained updated data for the thesaurus, with the idea being that we could check the erroneous dates against this.  However, the spreadsheet was created for a later project than the BTH and had both a different structure and different data.  For example, some categories in the online BTH were not included and many categories in the spreadsheet featured different or larger numbers of lexemes.  The dates were in a different format, featuring ‘ante’ and ‘circa’, plus a question mark to denote other uncertainty and a plus to denote continuation.  The BTH features none of this – just start and end dates.  The spreadsheet also featured no links out to the MED and the AND, only links to the OED.  We did wonder whether we should replace the online BTH with the data from the spreadsheet but all of these issues mean this just wouldn’t work.  Instead we decided that I would (at some point) write a script to identify lexemes in the spreadsheet that are not in the online BTH and we can see about incorporating them.  In the meantime I fixed the 197 lexemes that had their dates the wrong way round.

Also for the BTH this week I implemented an option to order the lexemes in a chosen category alphabetically, by first attested date or length of attestation (within the AN or ME section), where previously all lexemes were ordered alphabetically within each section.  This is something that was raised at the workshop, and something I wanted to implement as it’s a useful feature.  I’d already included this option in the main HT and parts of the code for it were lurking in the BTH code in an inactive state, although I needed to rework this as the main HT handles dates in a more complex manner.  The update required changes to the database, the CSS, the PHP and the JS scripts, but it’s all now live and the site remembers your choice during your session, so if you select ‘length of attestation’ in one category and then navigate to another this is remembered.  Below is a screenshot showing a category with the lexemes ordered by length of attestation:

This week I met with Jennifer Smith to discuss the talk we’re giving about Speak For Yersel in Edinburgh in a couple of weeks.  We had a good chat and made a plan about writing our respective sections.  I then spent about a day preparing the slides and text for my section and sent everything over to Jennifer so she could work on her parts.

Also this week I did a little bit of work for the AND, updating links from AND entries to the DMF, as their site has changed, which broke all our links.  I thought I’d found a way to link through to their corresponding entries but unfortunately their URLs now include a session variable that expires after a while, and the URL doesn’t work without a valid session.  This means it’s not currently possible to link to their entries so for now I’ve had to remove the links.  Apparently they are working to fix things so hopefully we’ll be able to reinstate the links at some point.

On Friday I met with Deven Parker to discuss her Playbills project and the requirements document I sent her before Christmas.  We discussed a few issues that had been raised in the feedback on the document and made a plan for the coming weeks, during which I will begin to work with the data and will start developing the online resource.

Other tasks I tackled this week included replacing the data I’d uploaded for the VARICS project last week with a new version I’d been sent, and also making several tweaks to the code and content of the lookup feature.  I also changed the language abbreviation ‘Ga’ to ‘Ir’ in the place-names of Armagh content management system and fixed a typo in the Hummell edition on the Burns website that went live before Christmas.

Week Beginning 5th January 2026

My first week back after the Christmas holidays was mostly taken up with travelling to and attending a workshop in Zurich hosted by the ‘Waxing and Waning Words: Lexical Variation and Change in Middle English’ project (https://www.waw-me.uzh.ch/en.html).  This project will be producing a Middle English thesaurus comparable to the Bilingual Thesaurus of Everyday Life in Medieval England (https://thesaurus.ac.uk/bth/) that I was responsible for developing back in 2018, and over the past year or so I’ve been helping out the project’s developer by sharing the BTH code, some sample data, and discussing how it all interoperates.

The workshop was a great opportunity to meet the project team and to work with their developer Tony Harris in person.  Working together in person is considerably more effective than communicating by email or even via online video calls and it was hugely productive.  We spent at least a day of the day and a half workshop working together and Tony’s knowledge and understanding of the system and its data structures increased massively during this time.  We worked with an initial dataset that the project team has created for the semantic domain ‘law’ and by the end of the first day we had created a pathway for importing this data into the thesaurus structure, meaning it could be searched and browsed in the same way as the BTH.  We also created links out from the headwords to the Middle English Dictionary.  Tony was then able to then apply this workflow to another semantic domain (medicine) and was able to demonstrate a working online resource to the other workshop participants the following day.  He should now have everything he needs to process the project’s data an integrate it into the thesaurus as the project proceeds.

It was great to be back in Zurich again, having attended a workshop there some three years previously, but our journey to and from Zurich did not go at all smoothly this time, due to some rather severe weather conditions.  There are no direct flights from anywhere in Scotland to Zurich so we had to change flights at Heathrow.  Unfortunately due to delays we missed our connecting flights both on the way out (on Tuesday) and the way back (on Thursday), which made for a lengthy and rather stressful journey.  This was especially bad on the return journey as our connecting flight was the last flight of the day from Heathrow to Glasgow, meaning we had to stay overnight in London and get an early flight back on Friday morning.  This was all pretty exhausting, but we did at least finally get back to Glasgow safely and despite the travel difficulties the workshop was worth it.

I only had time on Monday and Friday afternoon to work as usual this week, and some of Monday was taken up preparing for my trip.  However, I did manage to get a few things done.  In the run-up to the Christmas holidays I’d been working with the Hansard frequency data and at the start of the holidays I spent some time writing and executing a script to output the data for each year (199 years from 1803 to 2004, with some gaps) as a separate CSV file.  I tweaked the data a bit to change the three-character month text to an integer, as this makes it easier to order the data by month (e.g. so ‘apr’ doesn’t come first).  It also saves some space.  I set the script running overnight and it had completed by the morning.  It turns out we only have Commons data and nothing for Lords, with the 199 CSV files taking up 37.6GB (although when zipped this drops to 5GB).  I uploaded this to Teams so Marc and Fraser can access it.

On Monday I wrote a further script to export the remaining metadata tables from the Hansard database running on my laptop.  These tables contain information about speeches, speakers, parties, roles etc, and are connected through to the frequency data via the speech filename.  My scripts exported these tables as CSV files and I added them to Teams too.  They should be useful in allowing the frequency data to be limited to a speaker or group of speakers, or a particular political party and such things.

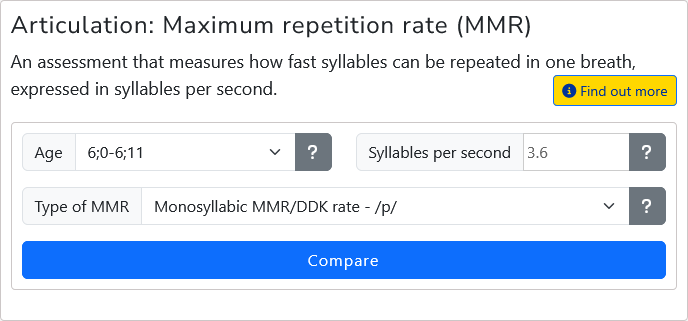
Also on Monday I spent a bit of time working on the VARICS project.  Before Christmas I was sent some further data for the lookup feature I’ve developed for the project, this time for maximum repetition rate.  It took quite a while to get this working as the new data has a different structure to previous lookup types.  Once selected the type then has several subtypes, such as ‘Monosyllabic MMR/DDK rate – /p/’ so I needed to ensure a further selection was added to the interface and also that this was taken into consideration when the data was being queried.  The data itself also included several new fields for ‘coefficient of variation’ that also needed to be stored and displayed.

I decided to create a new table to this new data type, populated it with the data from the spreadsheet I’d been sent and created new display and measurement analysis code for the new type.  The new display for the speech measure can be seen below:
When I returned to work on Friday afternoon I made some tweaks to the metadata for the Speech Star ‘MRI Modelled Speech Corpus’ (https://www.seeingspeech.ac.uk/speechstar/mri-speech-corpus/) that Eleanor Lawson had asked me to make.  I also began to investigate updating the BTH display of lexemes to add in options to order them by date and length of attestation in addition to alphabetically by headword, something we offer through the main Historical Thesaurus and we’d discussed at the workshop.  I wrote a script to generate the length of attestation and will hopefully implement the ordering options next week.

I also investigated an issue someone at the workshop spotted with some of the BTH lexemes having start dates later than their end dates.  It turns out that there are 197 such lexemes, which I exported as a spreadsheet and sent to Louise Sylvester for checking.  Hopefully it’s a simple case of the start and end dates getting accidentally added the wrong way round and a simple switch will sort things.